Showing entries for: Data Pipelines (show all)

Depth Data Mapping & Processing

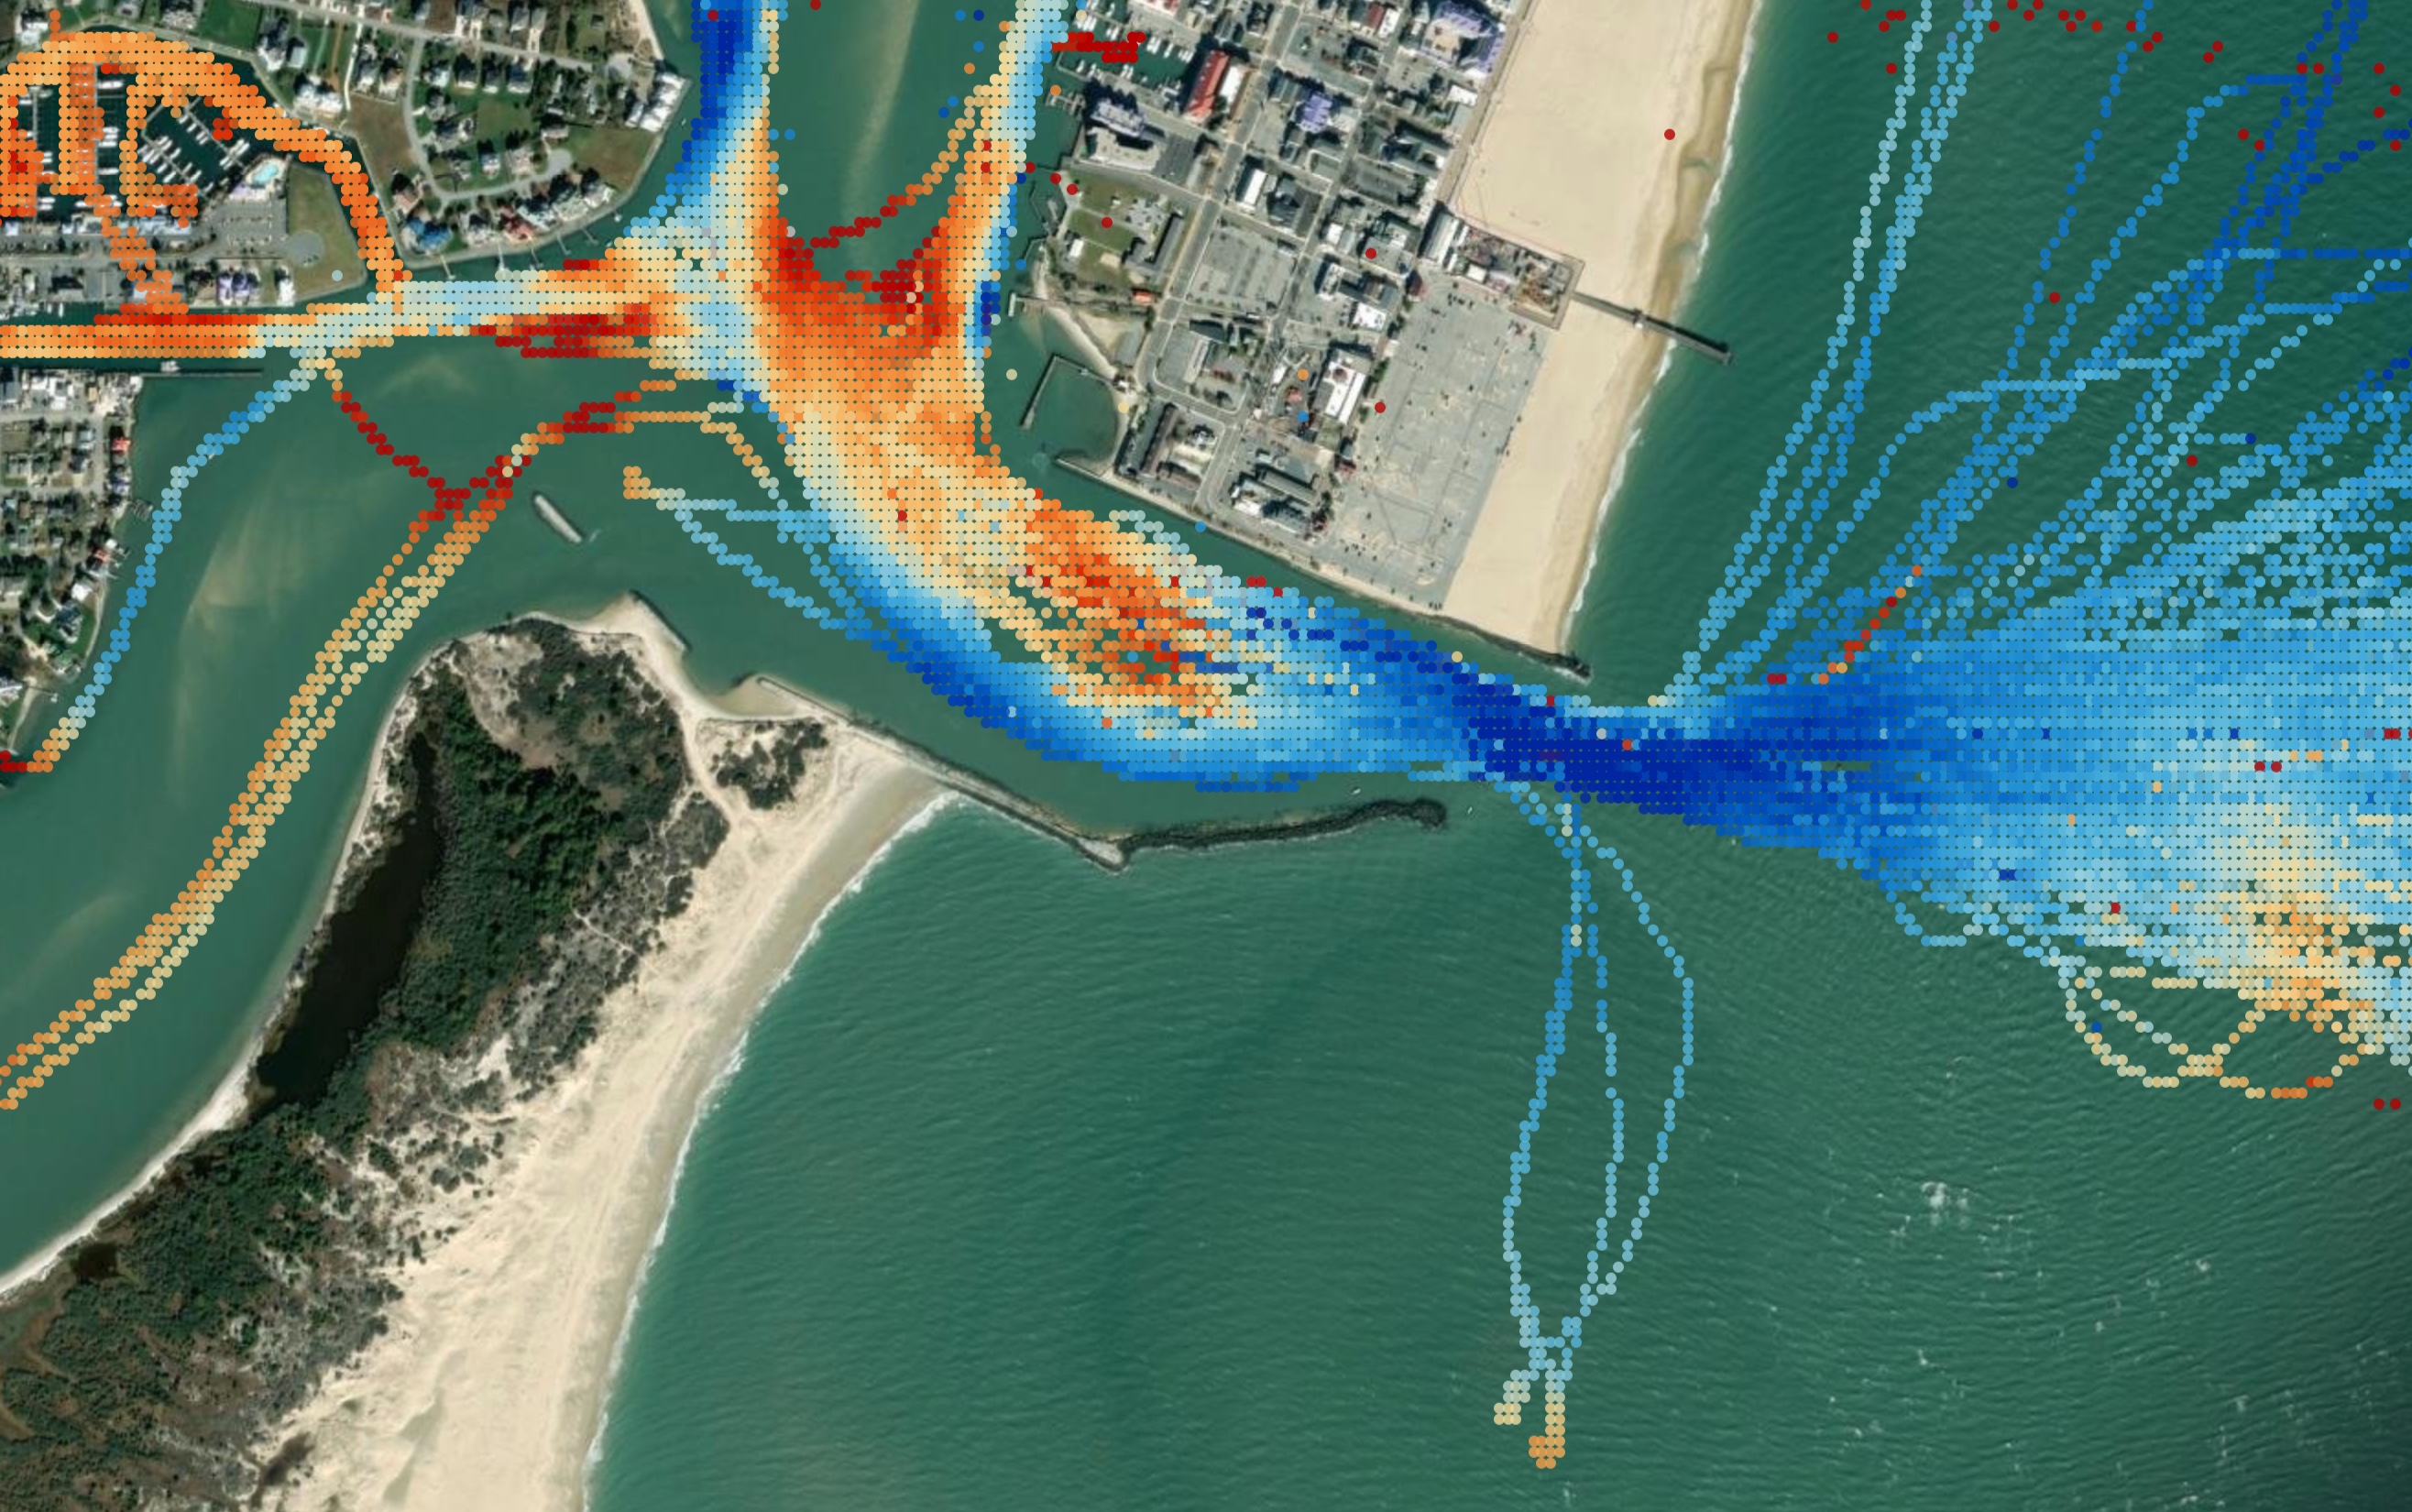
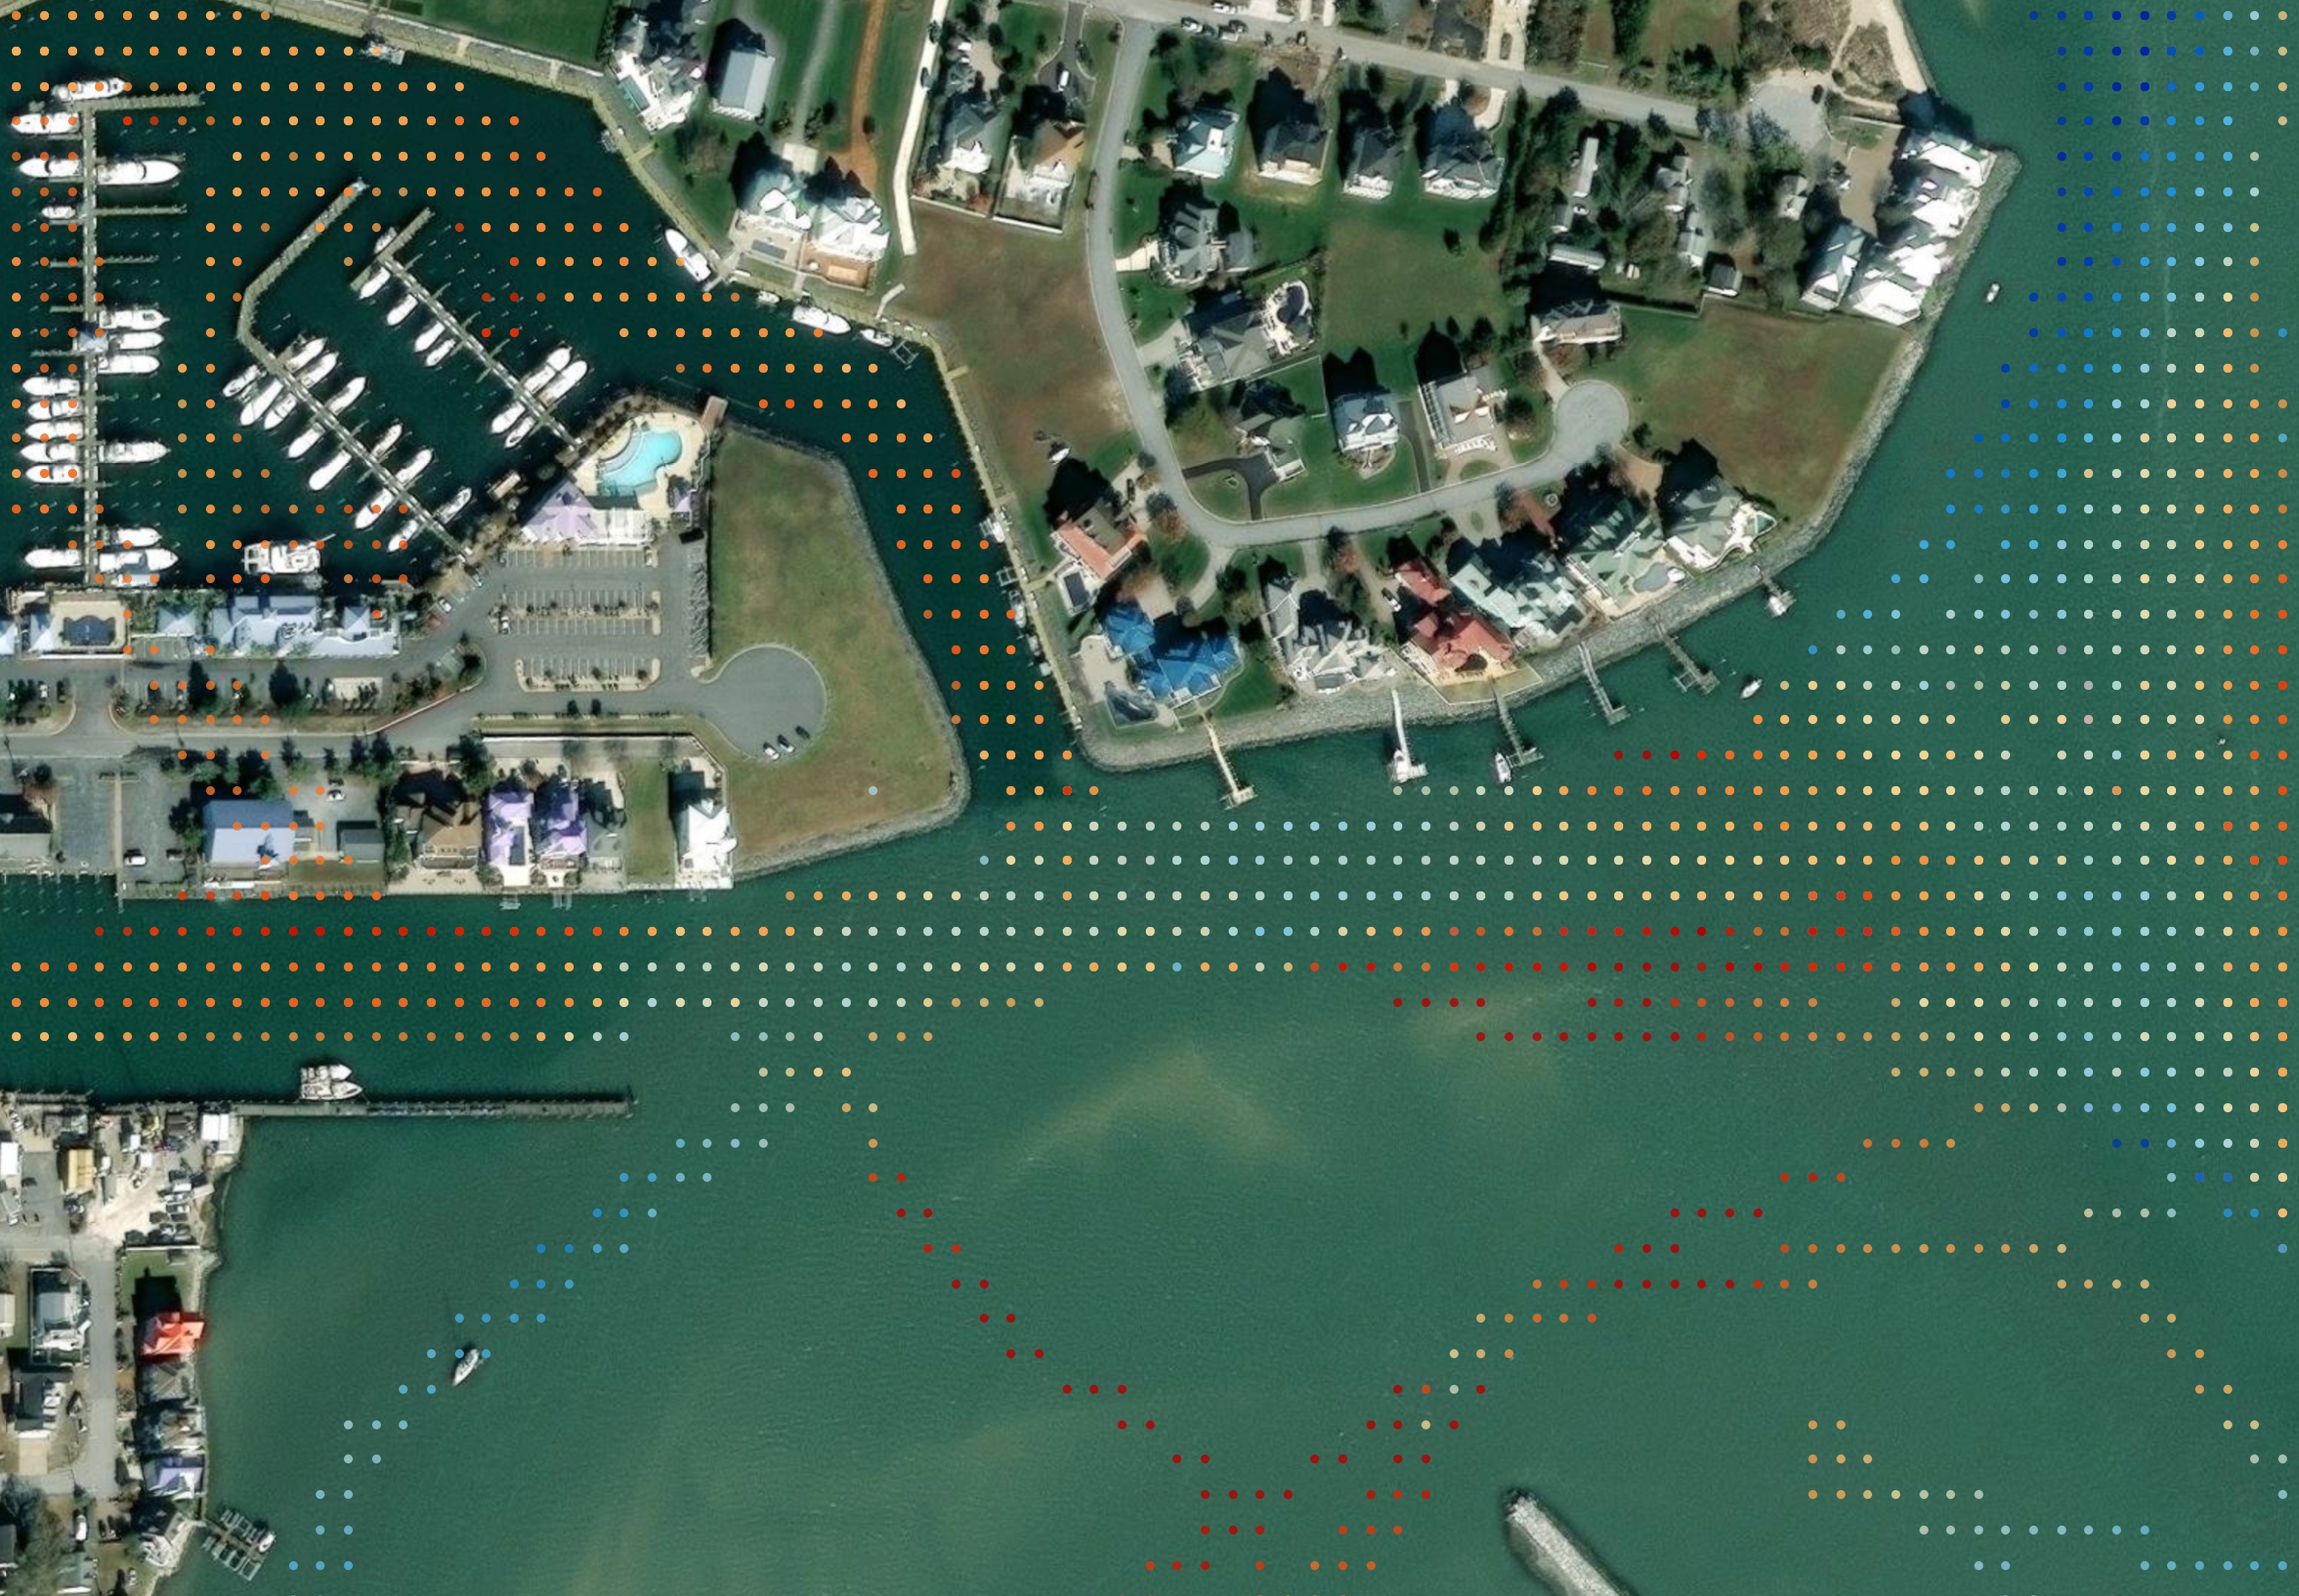
This past week I've been working with our data store at Canyon Runner to collect and process boat depth sensor readings from our fleet of boats.

Purpose

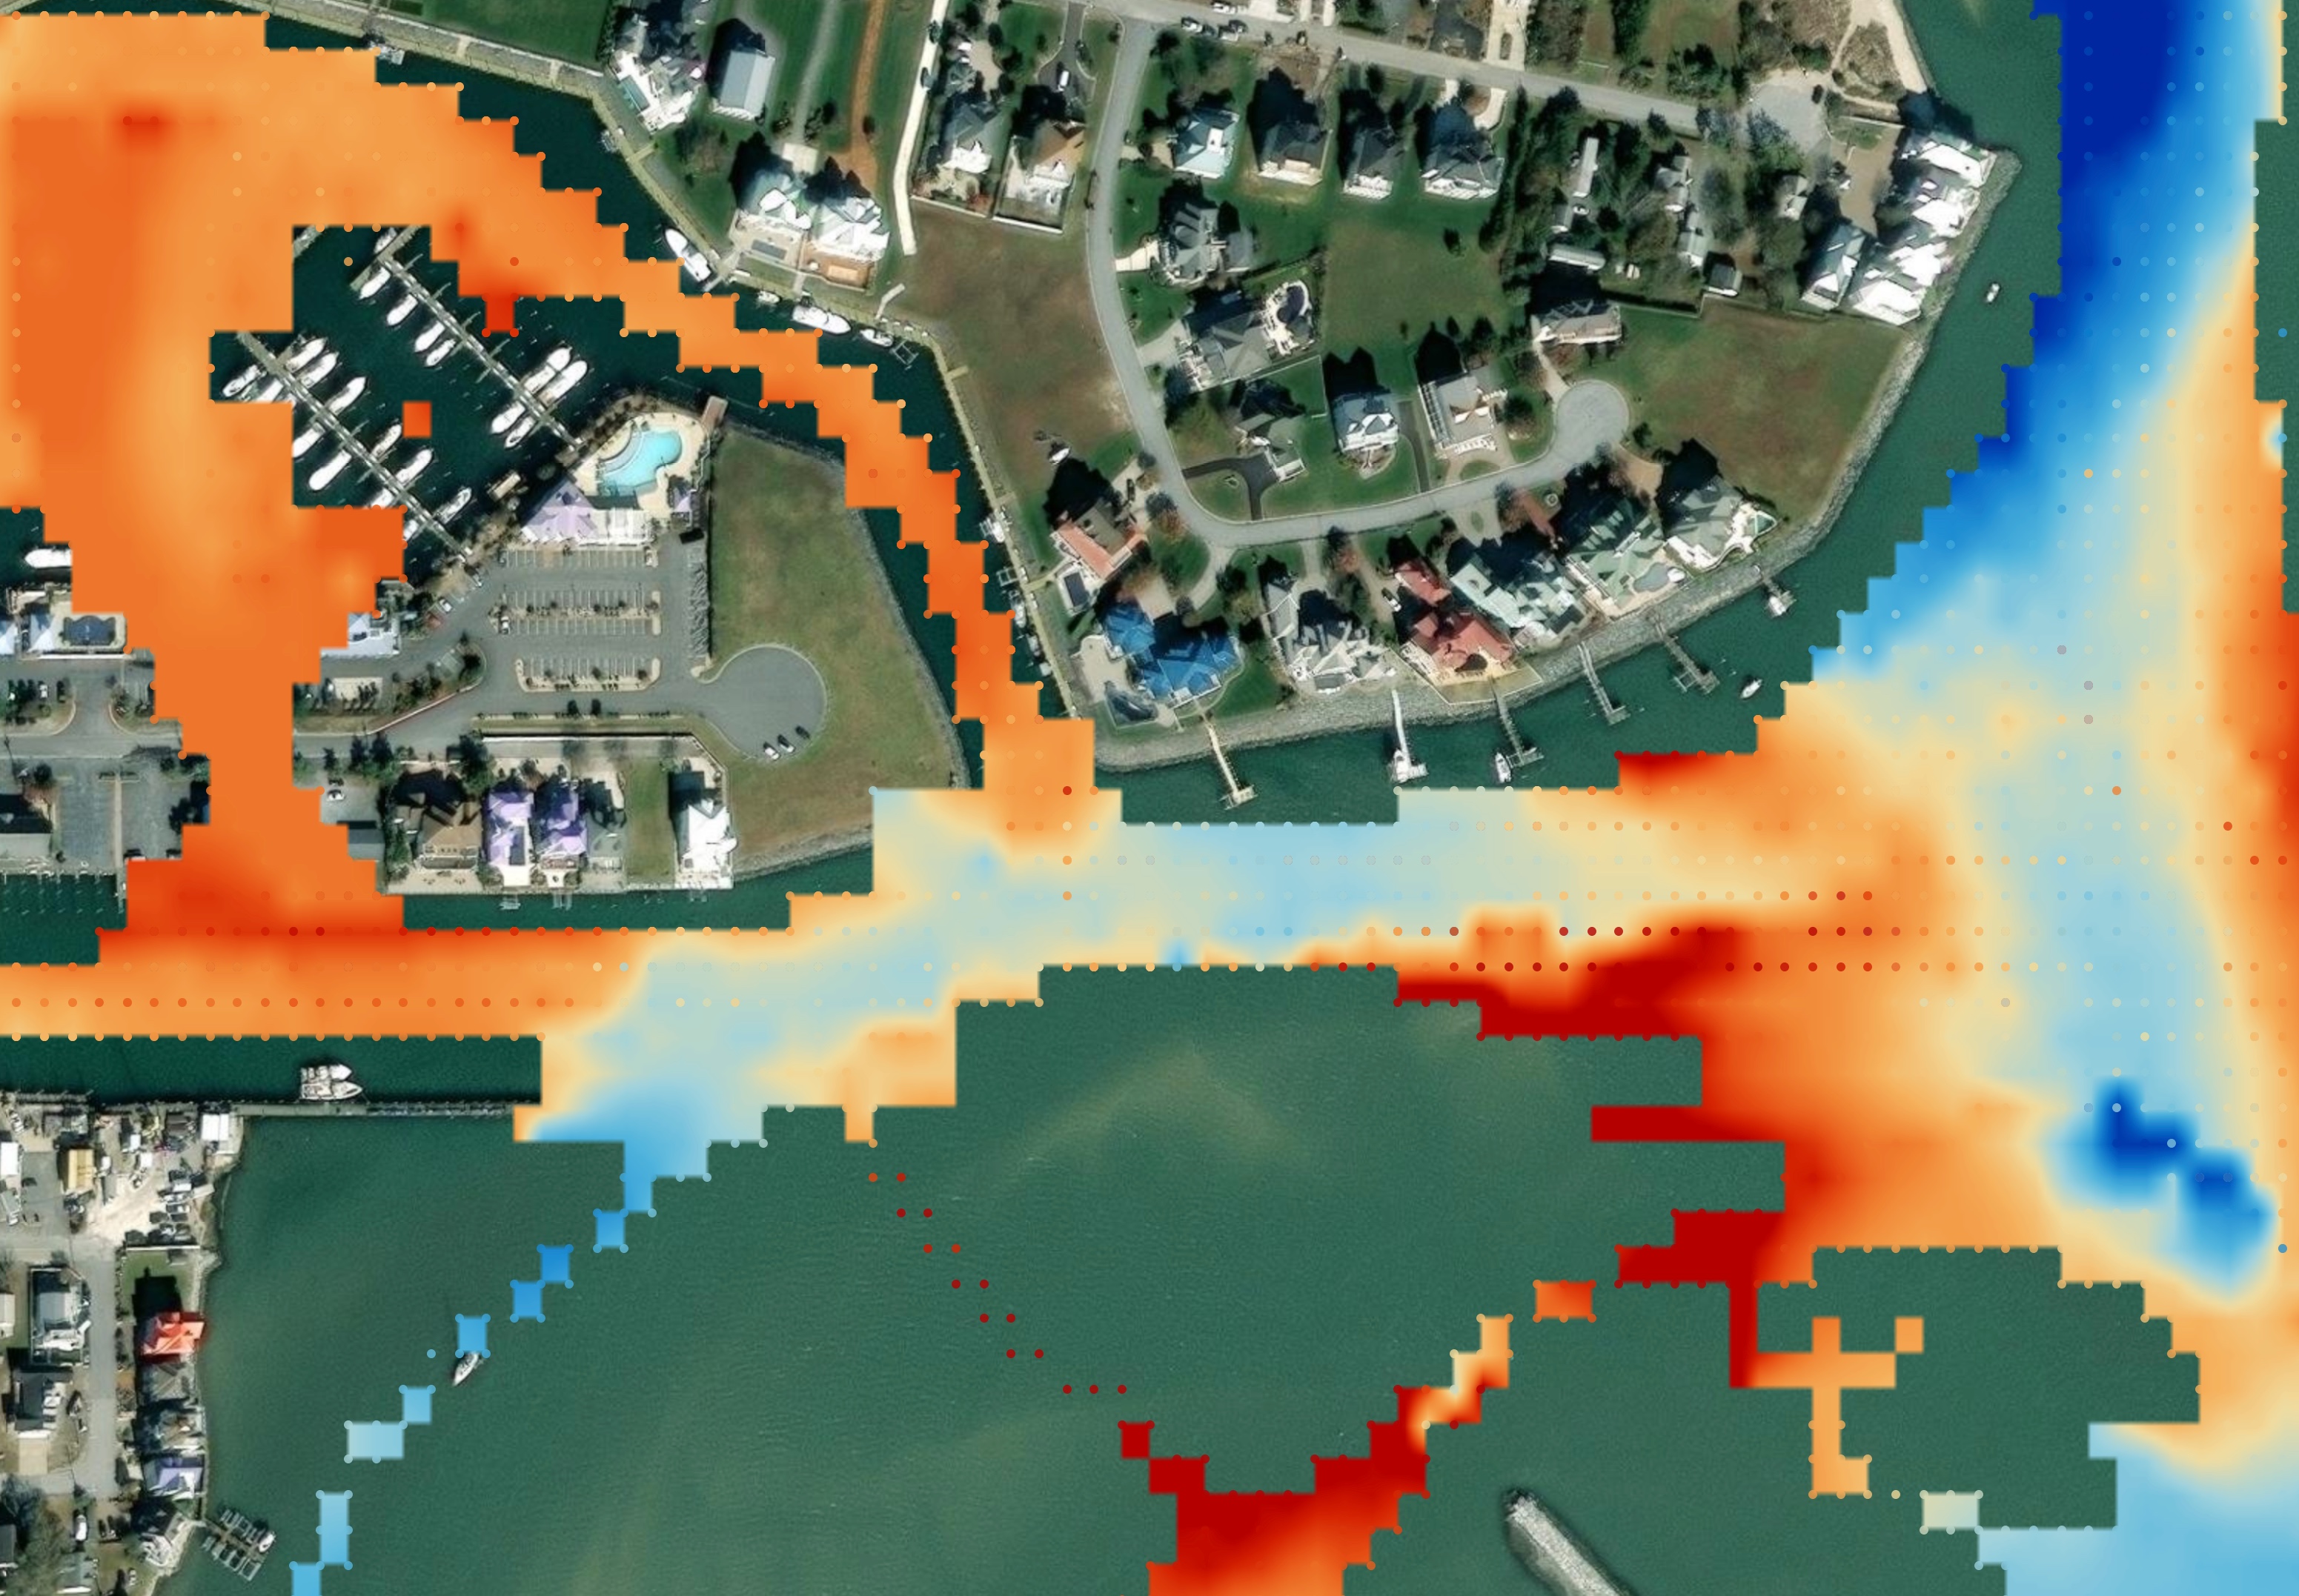
This work is preliminary research to determine if we have enough data to provide more real-time depth readouts and charts for our customers. The aim here is to provide more real time charting for inlets that often have rapidly changing underwater conditions after storm surges.

Approach

The approach here requires mapping our depth sensor readouts (which don't come with geo-coordinates) to the boats coordinate readouts aligned by time, with a sliding window of four seconds (an arbitrary time chosen to prevent data loss while still maintaining accuracy). These points then get mapped to a grid for consistency (see screenshots), and the median value is displayed and interpolated to create a relief chart.

This work is still ongoing, and is predominantly just research to see how feasible using this data will be to provide customers with more up-to-date depth readouts.

By the Numbers

A single inlet across a 6-month time span might have anywhere from 4-12 million data points depending on how much traffic is passing through that inlet. The goal here is to make it render on a map, while offering various data filters, and still keeping it performant.
Entry image Entry image Entry image

Career Matching Algorithm

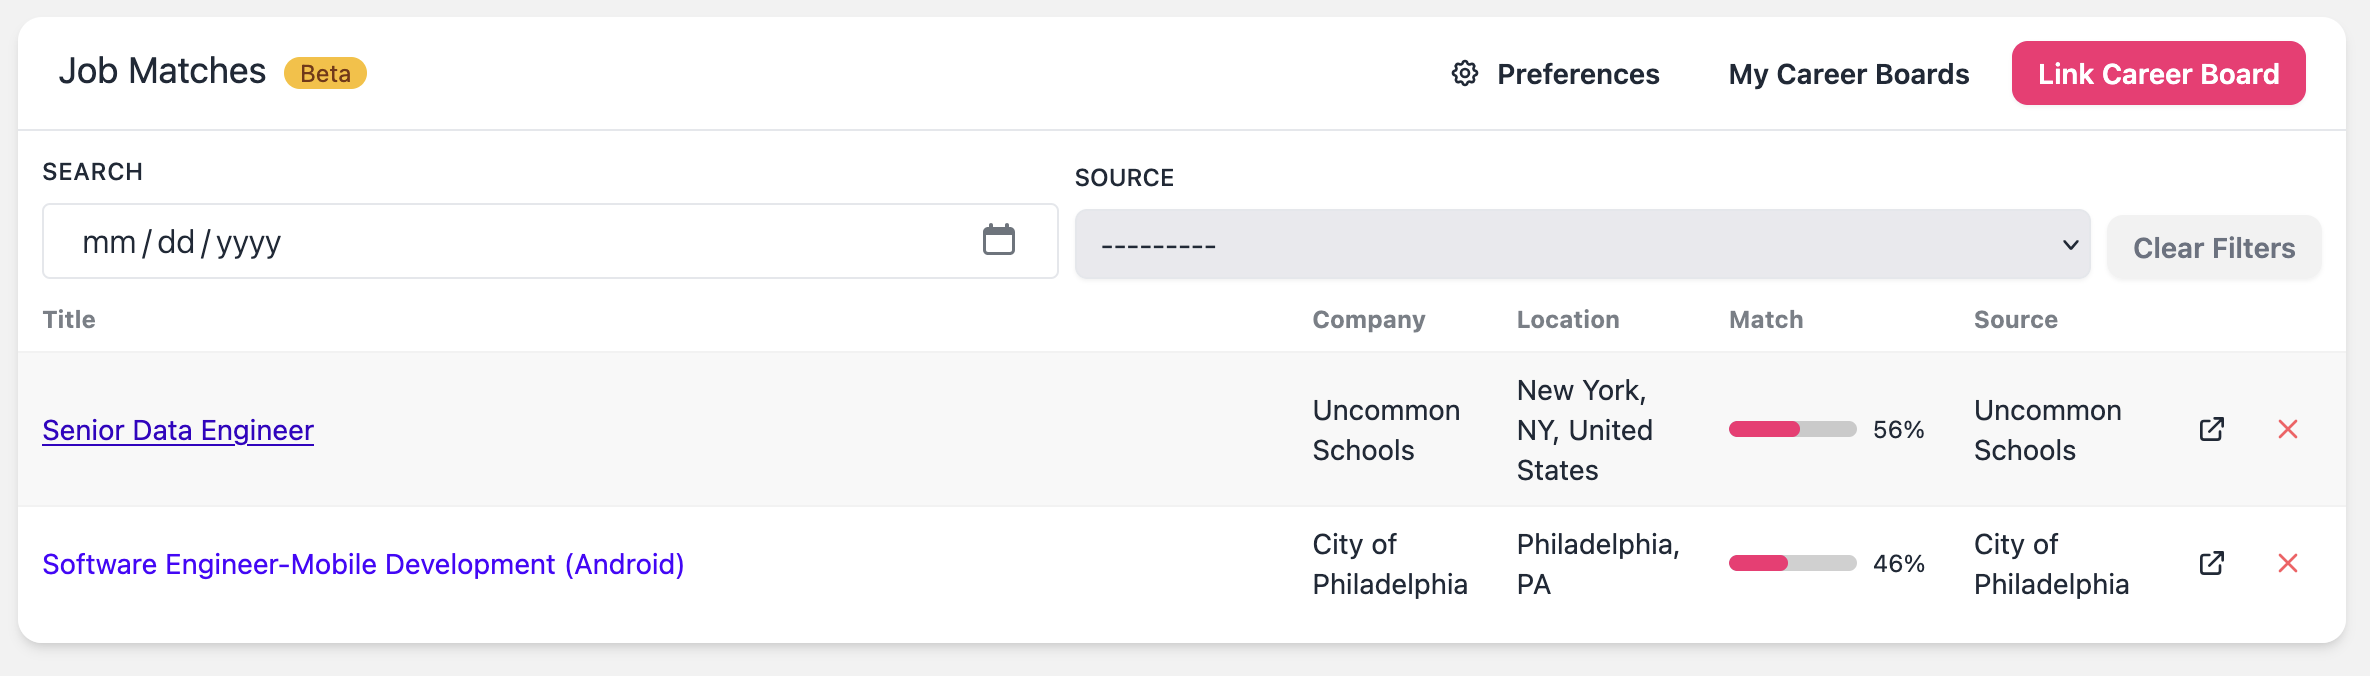
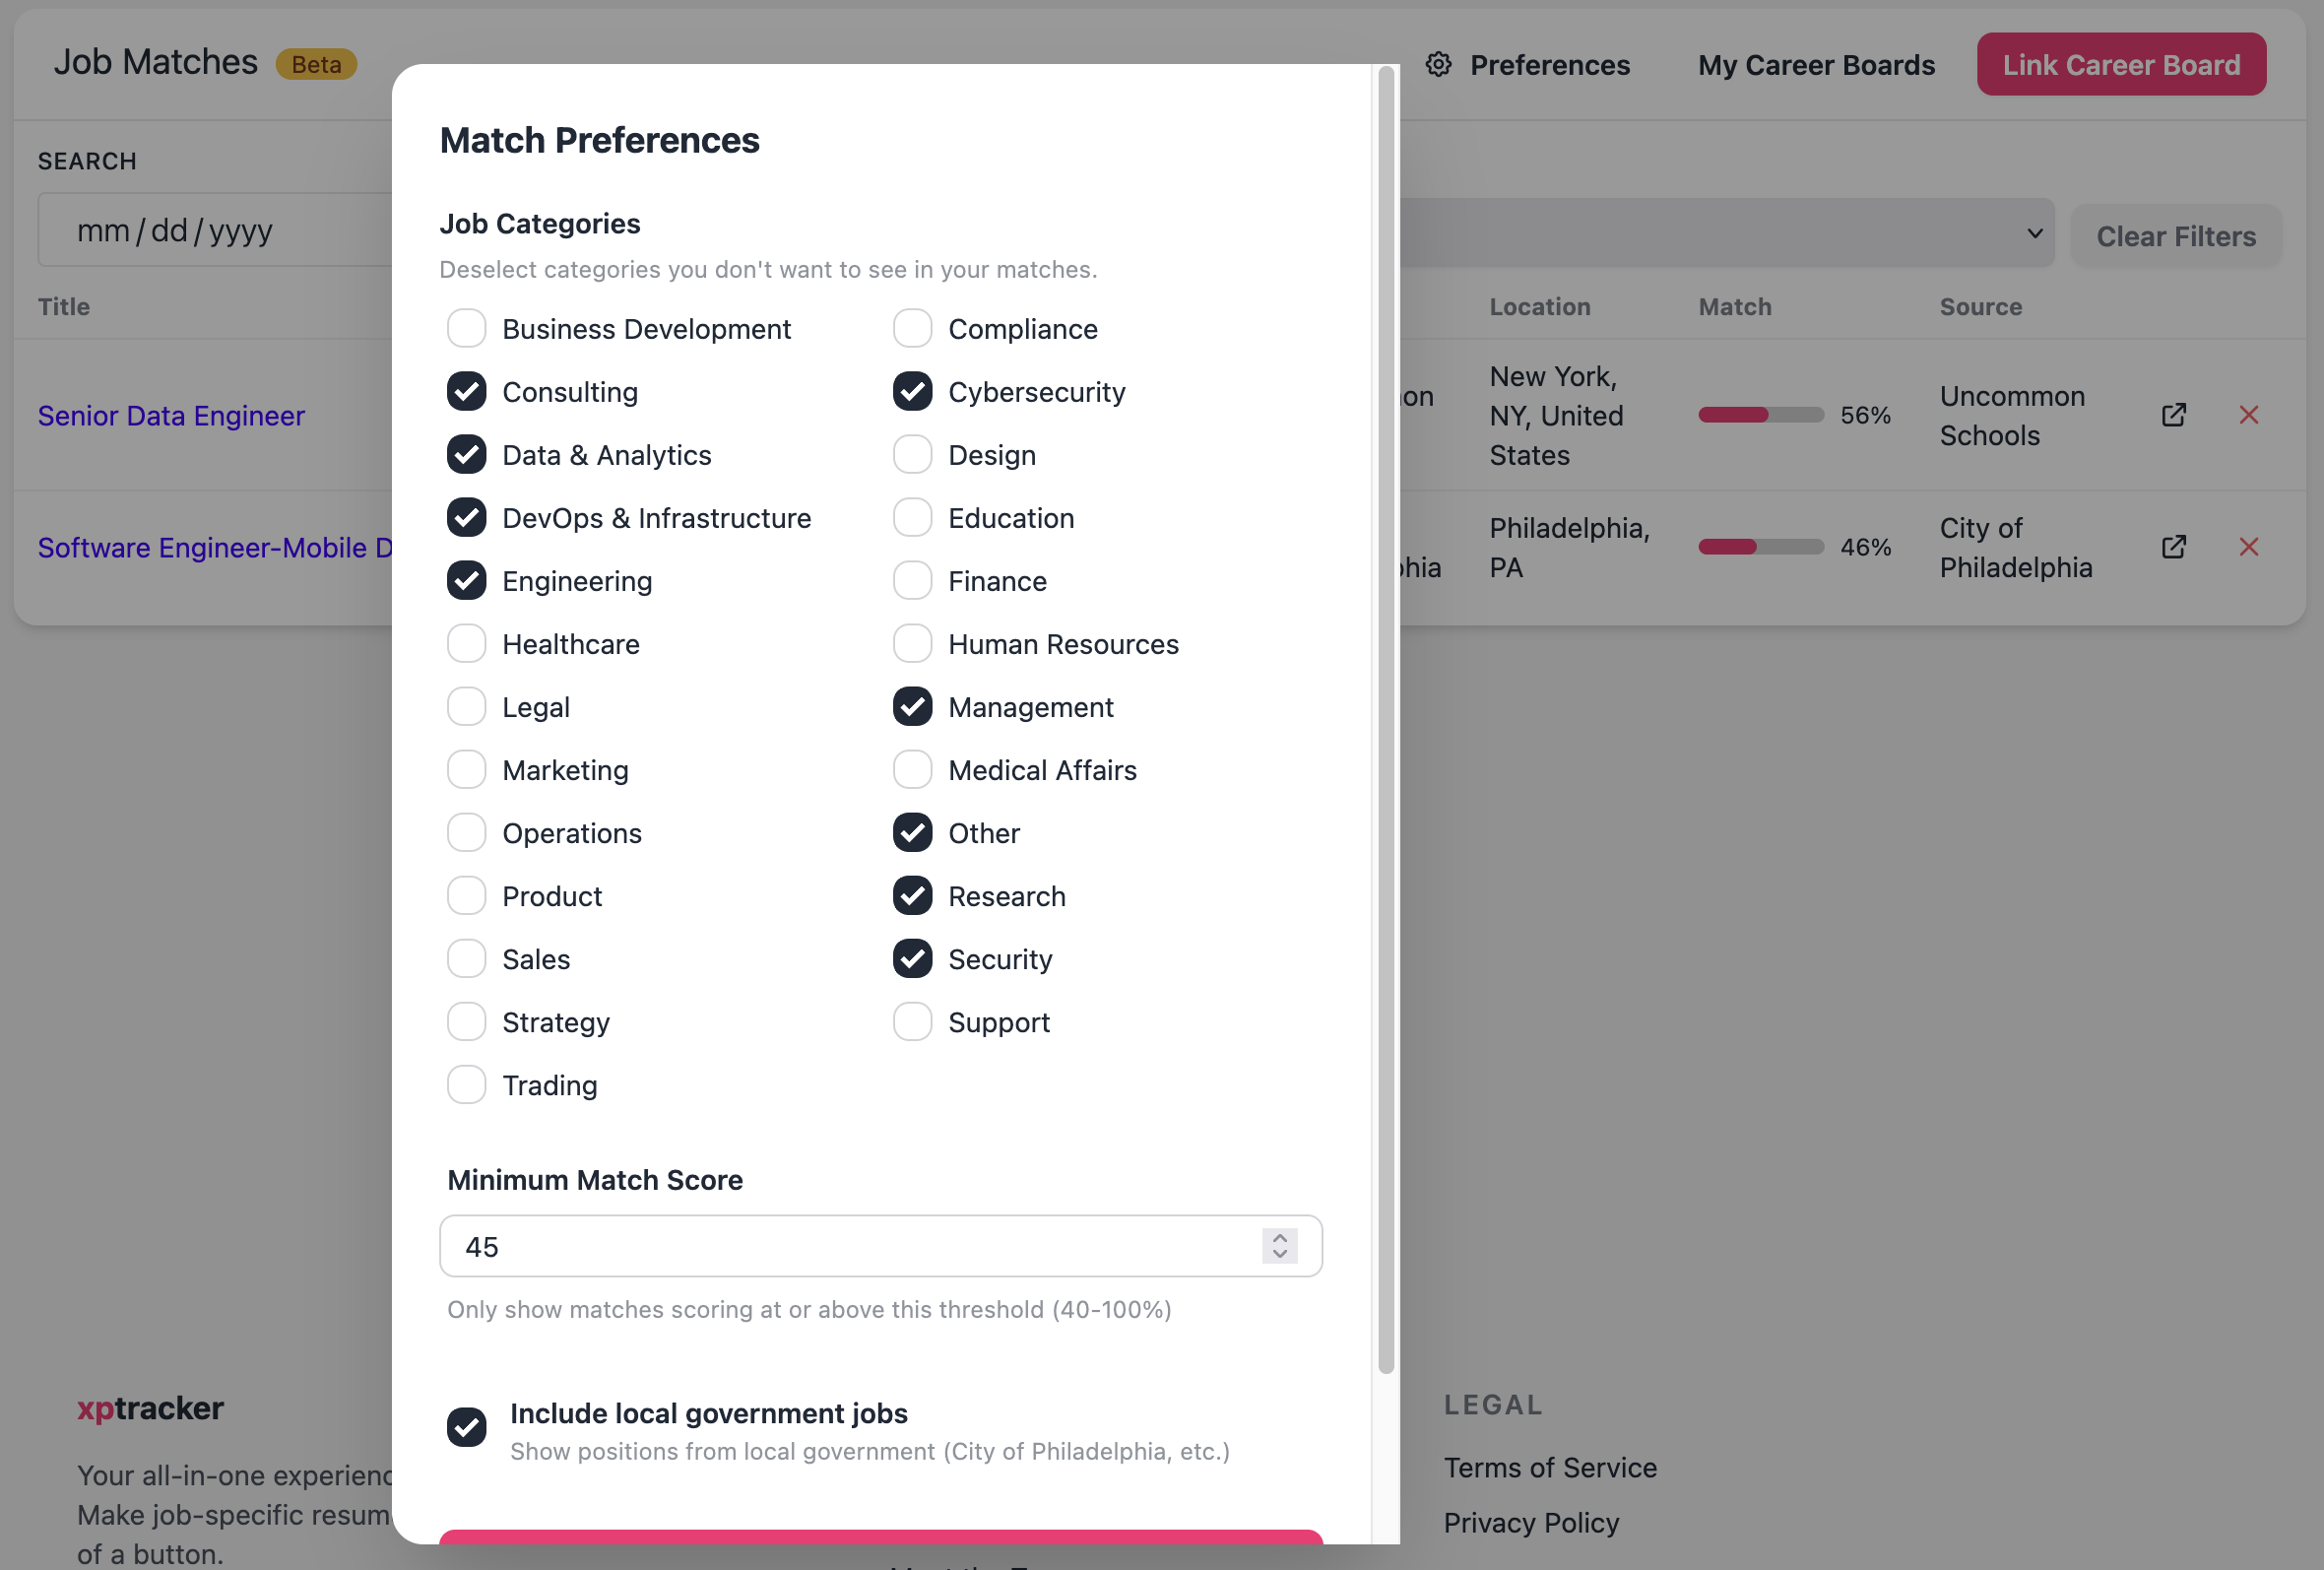
Working on a new data pipeline for finding and ingesting public job listings that then get matched to xptracker users by relevance. The feature is currently in beta, but the above screenshot offers a little sneak peak!

General Process

The overall pipeline covers several steps:
- Download public listings via publicly accessible API's.
- Store their various meta fields, whatever is available.
- Enrich stored listings using a lightweight AI model (like Claude's Haiku).
- Compute job matches to users with access to this feature.

Cost Cutting

Anything that uses LLM models in this way is bound to introduce an upfront cost, that's why we introduced checks into the pipeline that only poll for and tailor results to users who have access to this feature. Anything with heavy AI usage on xptracker will require a subscription to access in the future.

Entry image Entry image

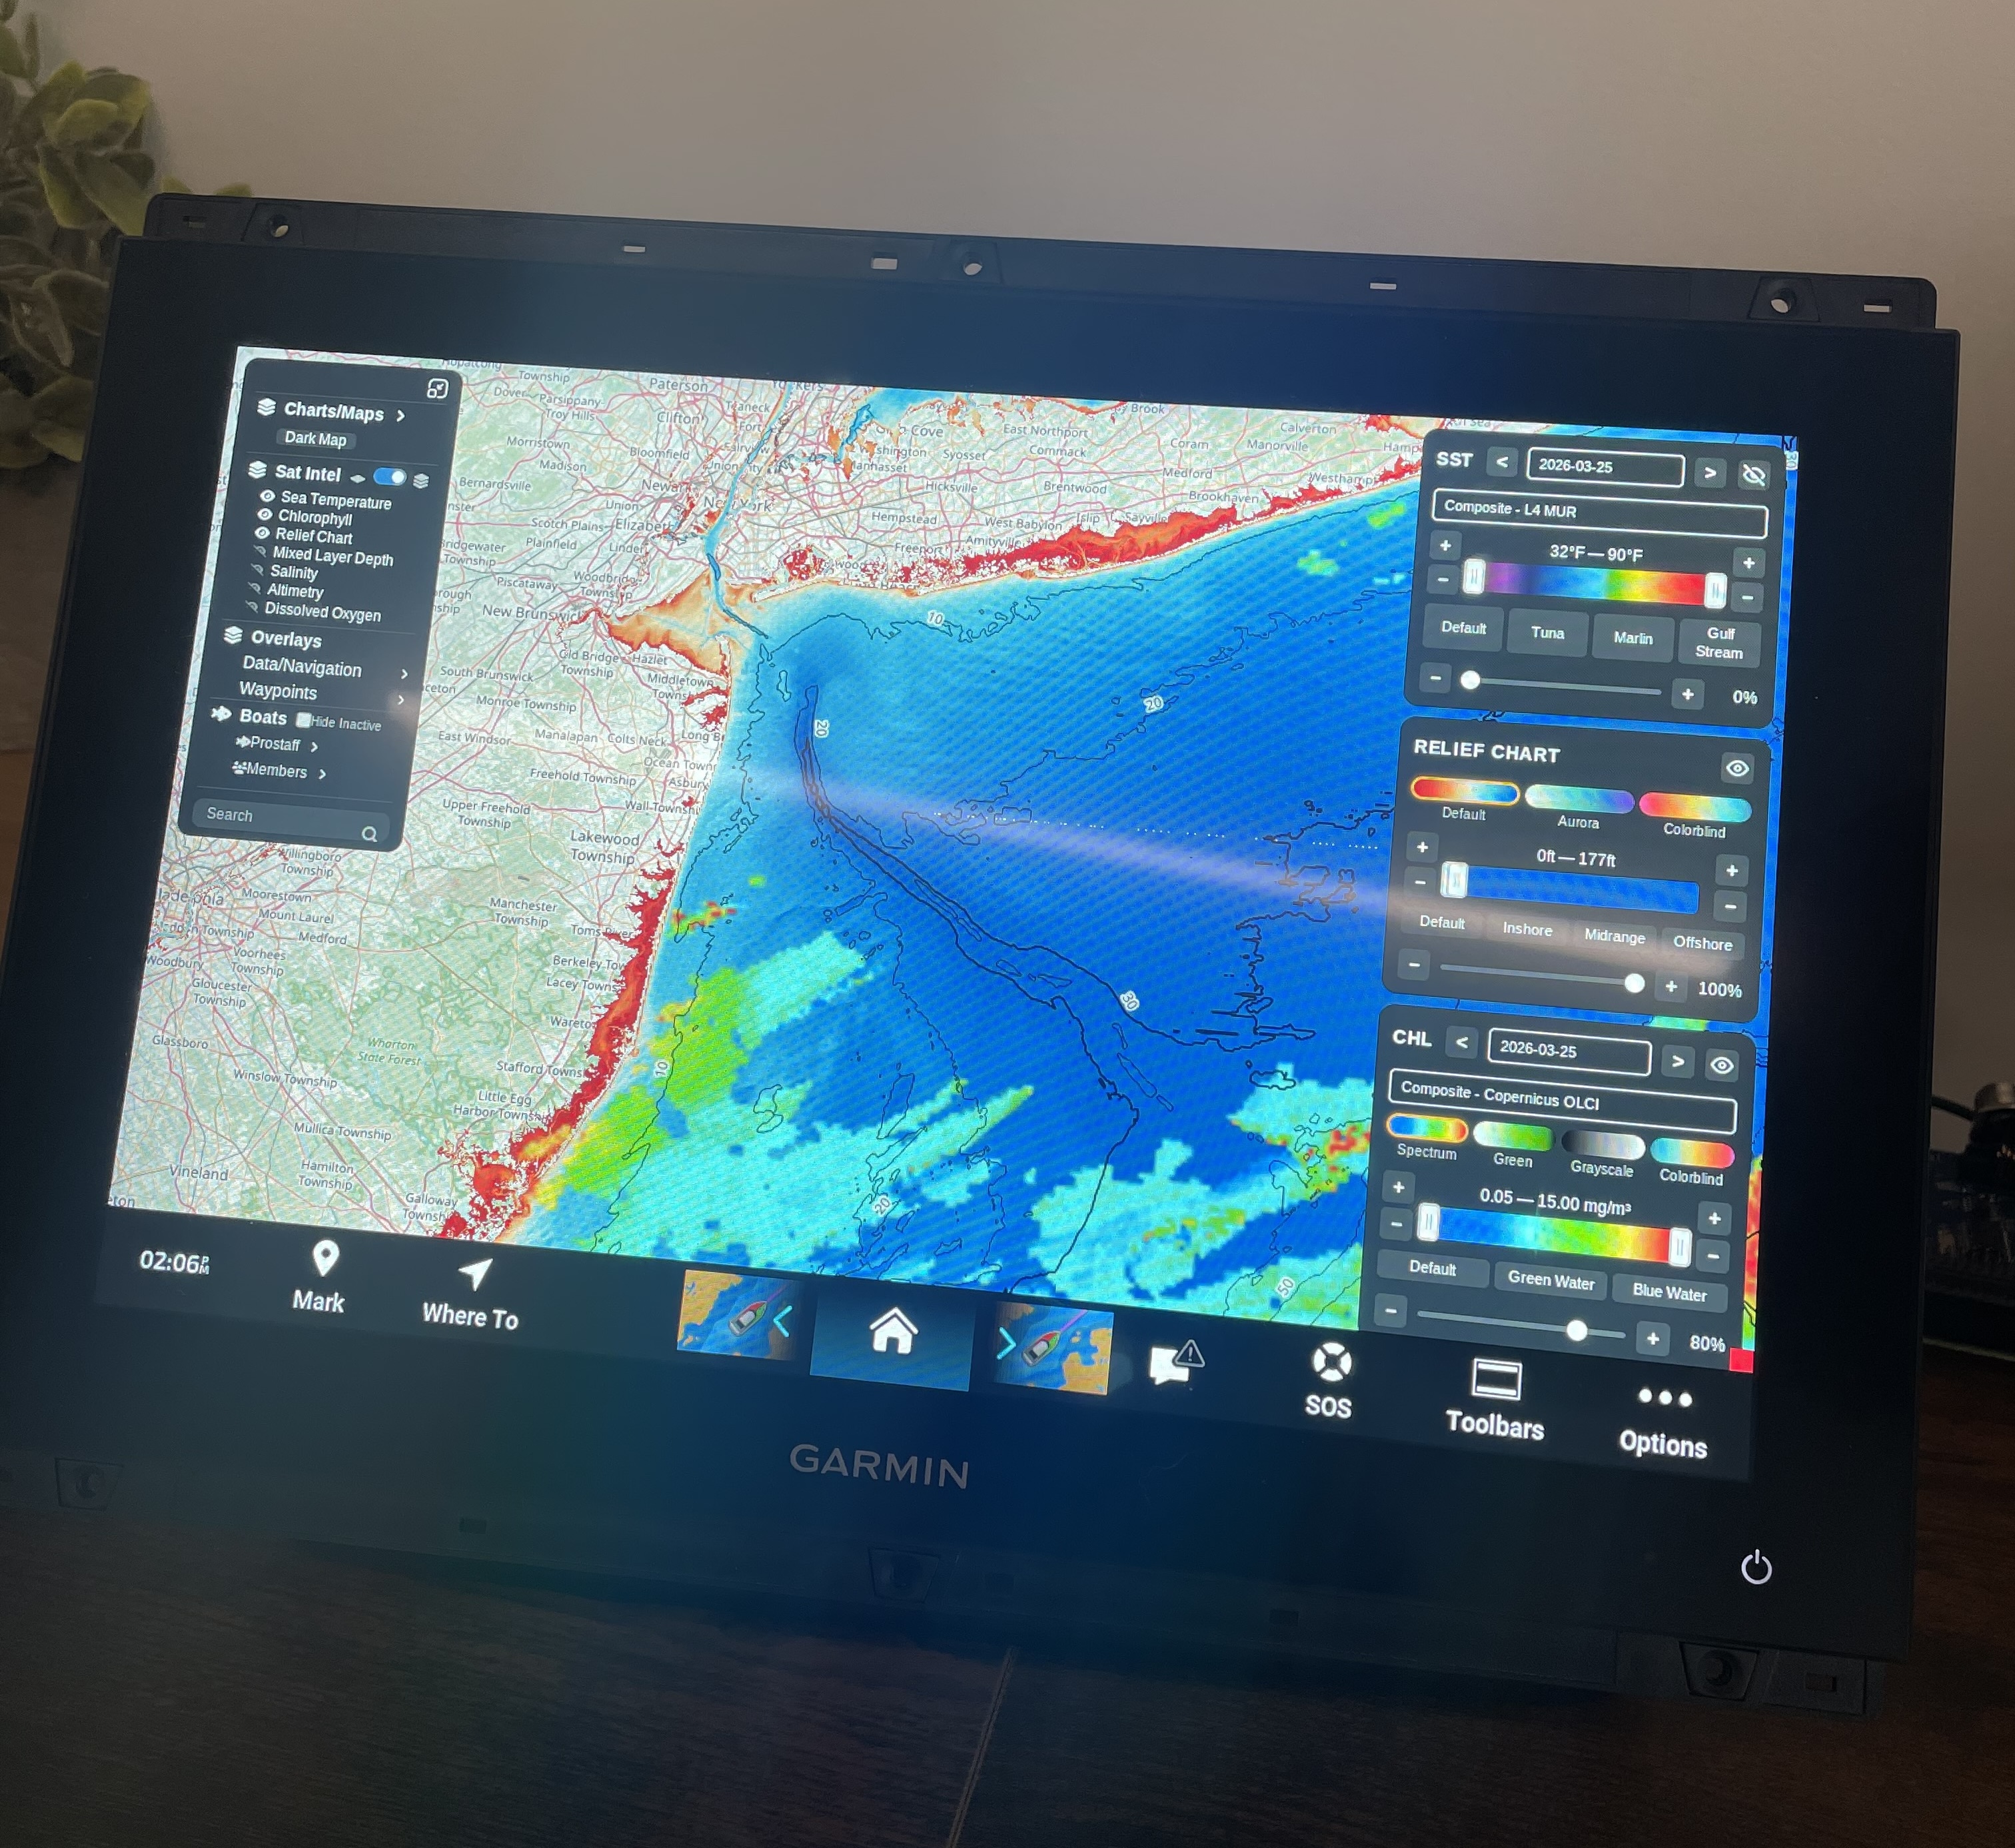
Loran Lines on OneHelm

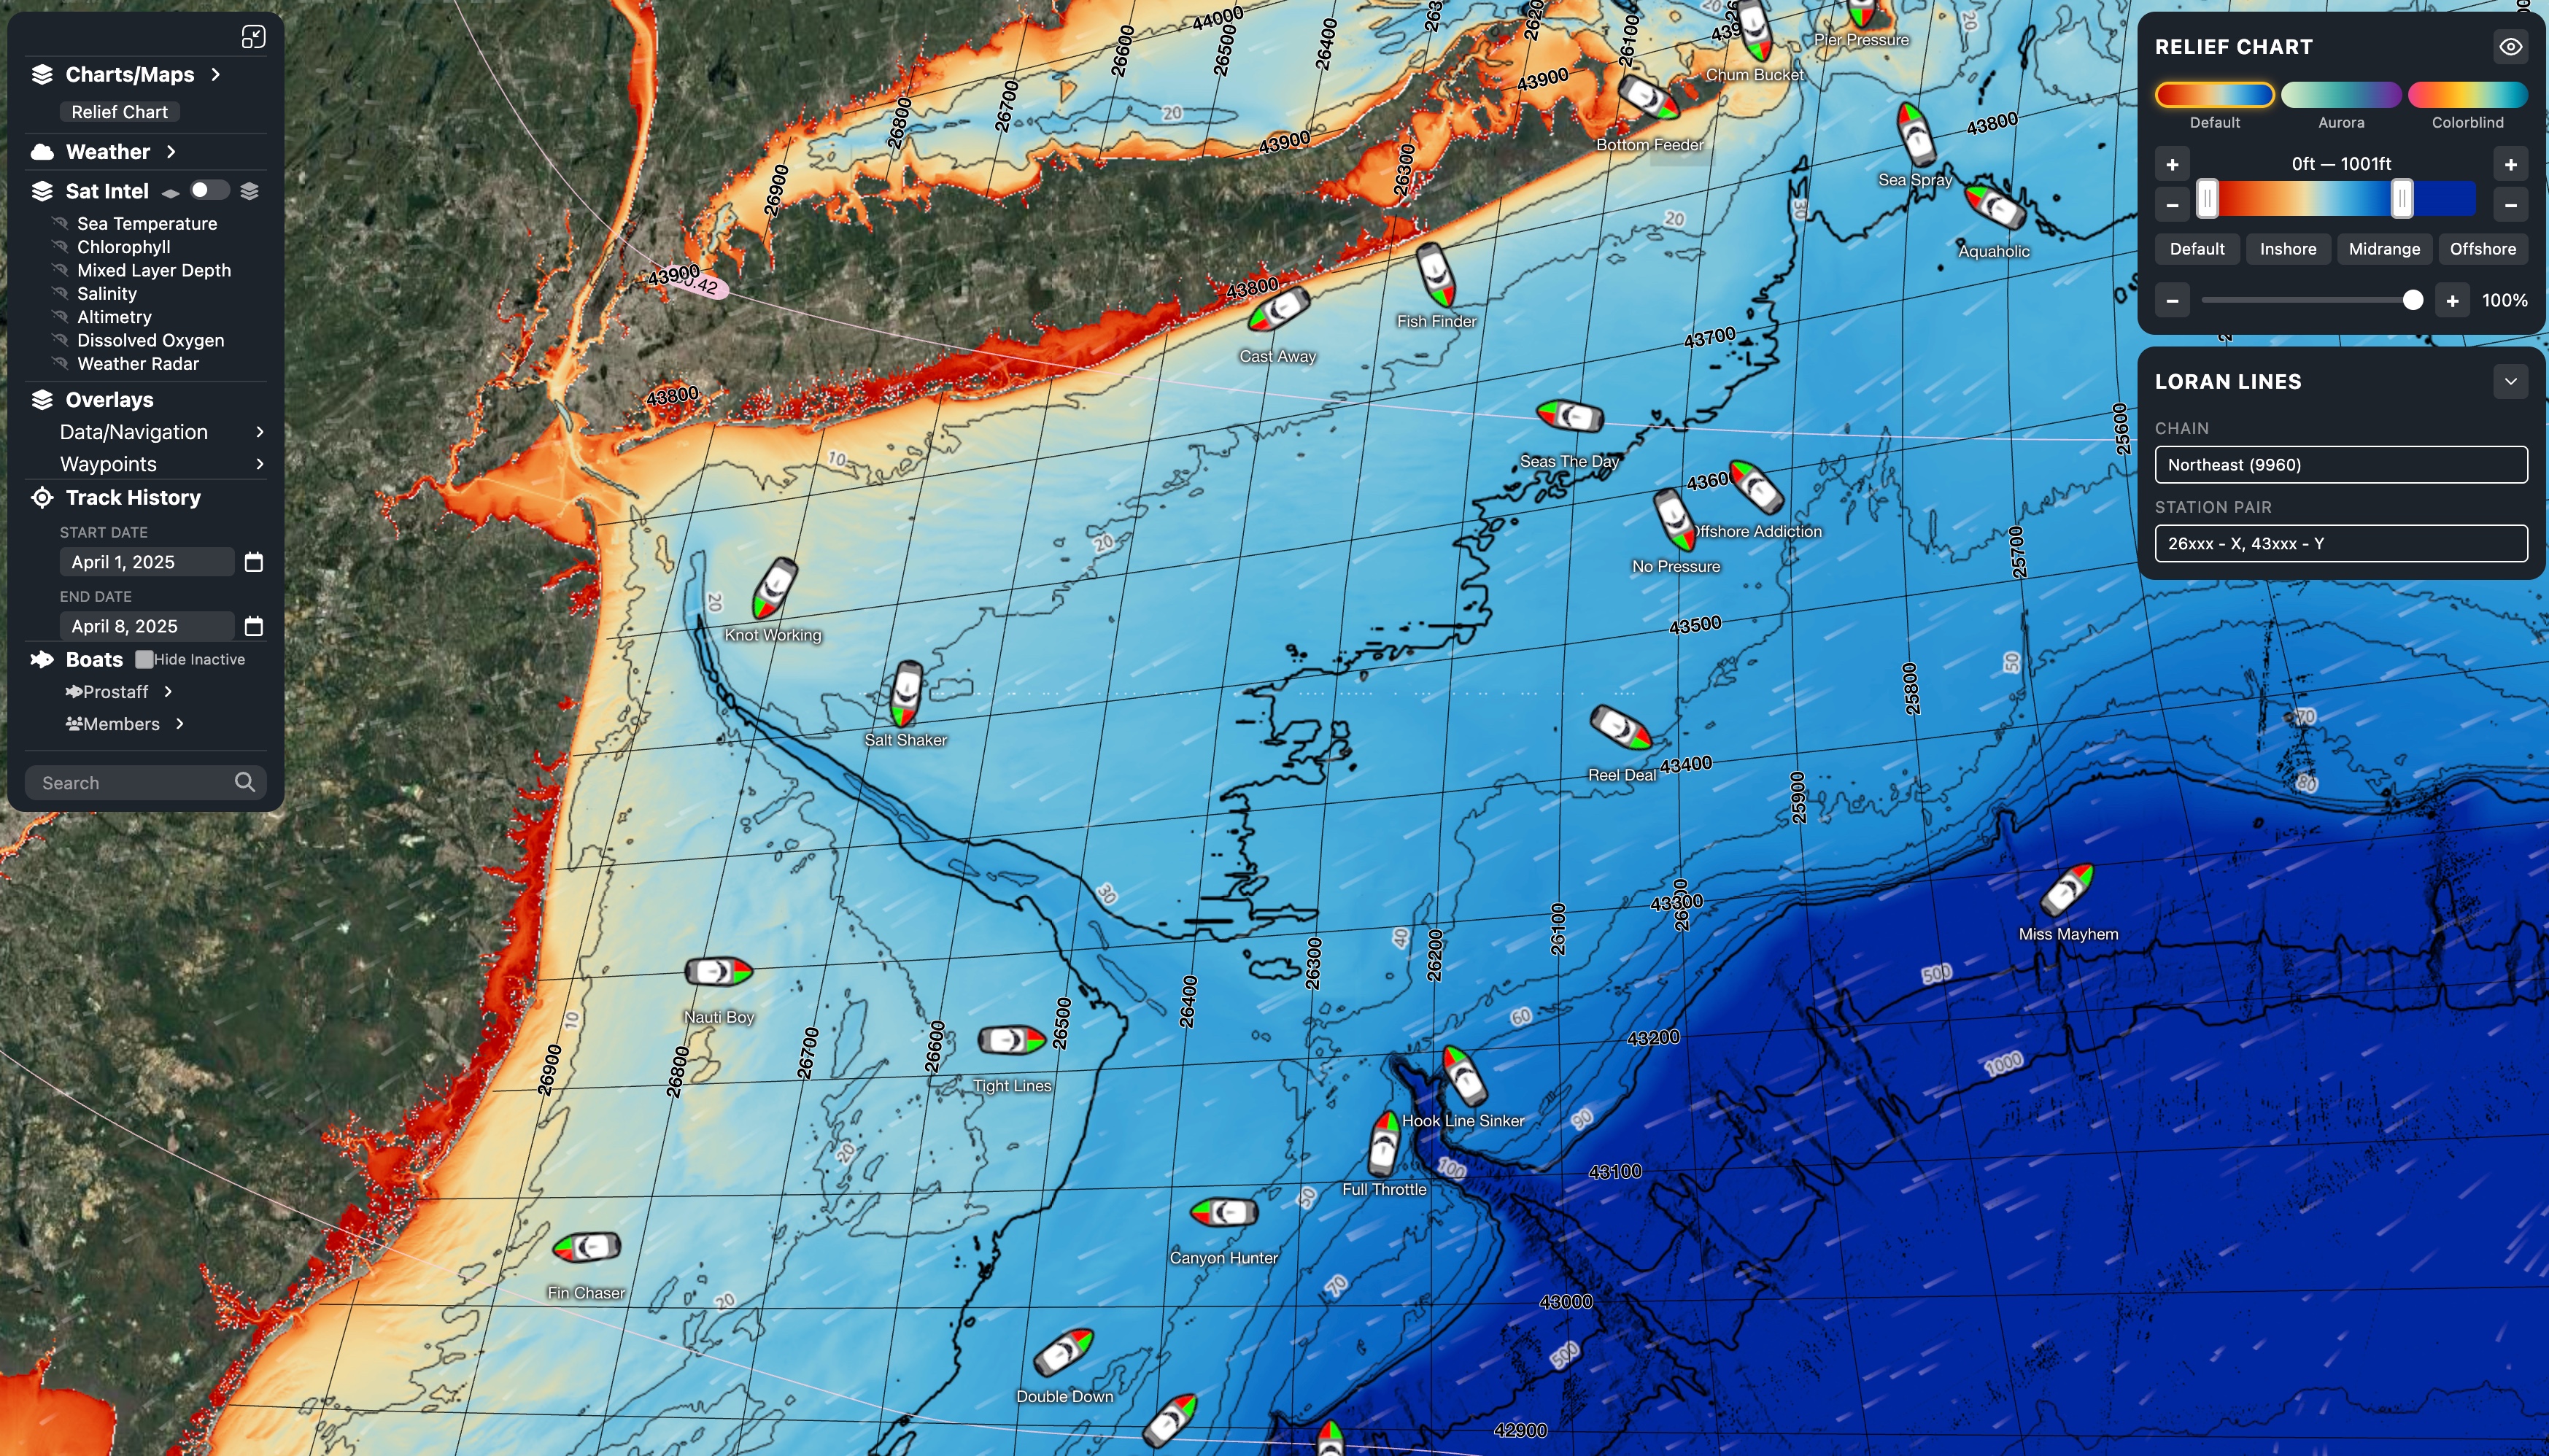
Introduced Loran lines for the Garmin OneHelm typescript application. Introduced various performance enhancements to reduce about 1kb of memory overhead to keep the application in-line with the OneHelm 150MB spec limit. Hyper-optimizations included reducing forced SVG layout counts from 2400 to 300, text alignment map pings from 600 to 300, and removed all 2100 event listeners entirely to reduce overhead further.

Event Listeners

Typically no one has to think about the overall number of web listeners their creating on their web page. Any modern device can support way more than even the most poorly optimized sites can truly throw at it; however, that's not the case for the Garmin device, which only allots 150MB of total RAM to any given OneHelm app. Removing the 2100 event listeners caused a noticeable drop in bootstrap times, and improved overall responsiveness (which unfortuntaely is still a work in progress overall).

Entry image

Garmin OneHelm Pipeline

Developed the Canyon Runner map's app from the ground up to support older webkits running on marine devices such as the Garmin OneHelm device. Created a custom lightweight typescript framework to help facilitate the 150MB RAM restriction onboard the device, and introduced countless performance enhancements to improve feel and responsiveness. Included a build and compile pipeline to auto-deploy the newly reworked app.

The typescript framework makes use of recurssive enclosures to create a more verbose and implied form of coding. For example:

CR           # Canyon Runner - Global Object
CR.MAP       # Map Module

Each module creates it's own logging handling and hooks into a global performance logging system. So for debugging on the out-dated Garmin webkit, we can access a log of all functions invoked and roughly at what time via:

CR.MAP.log("...", {...params}) # Logs only if running in _debug enabled environment.
CR.MAP.printLogs() # Prings all of the modules logs as a table.
Entry image

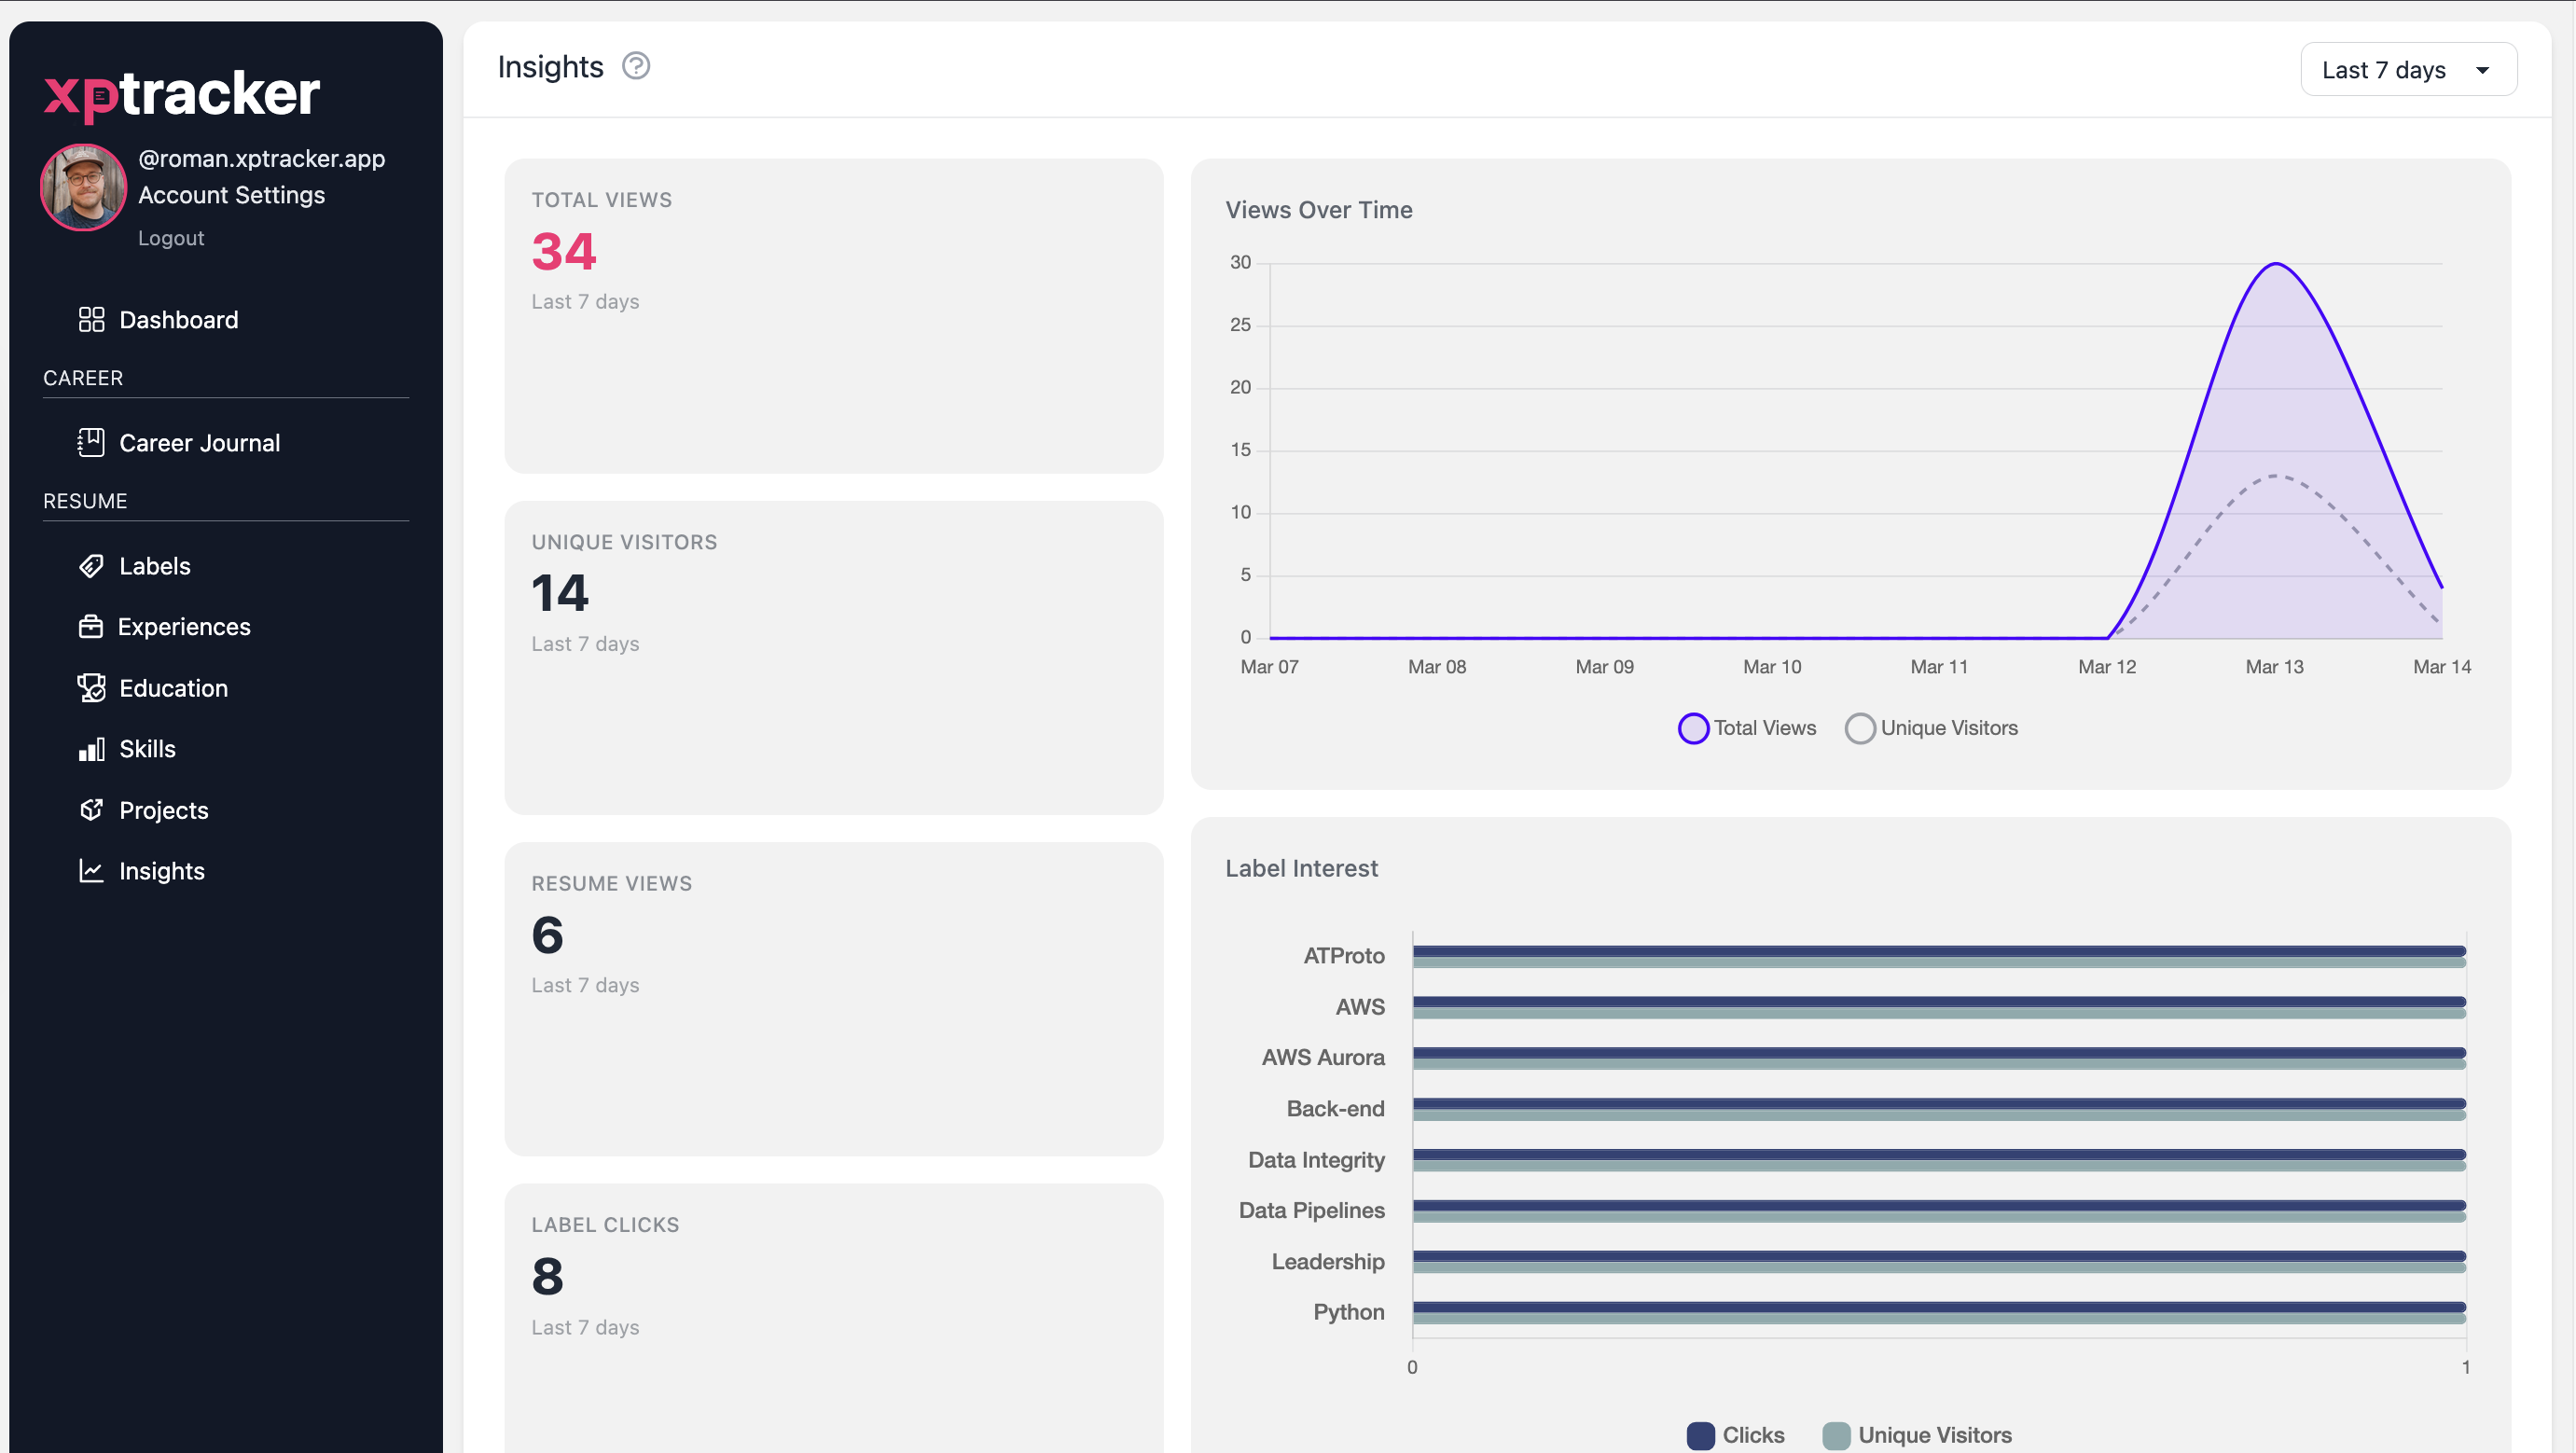
Resume Metrics

Added (anonymized) metrics gathering as a “pro” feature to xptracker. Allows users to see number of visitors to their resume and career journal, as well as track which labels people are most interested in.

Entry image Entry image

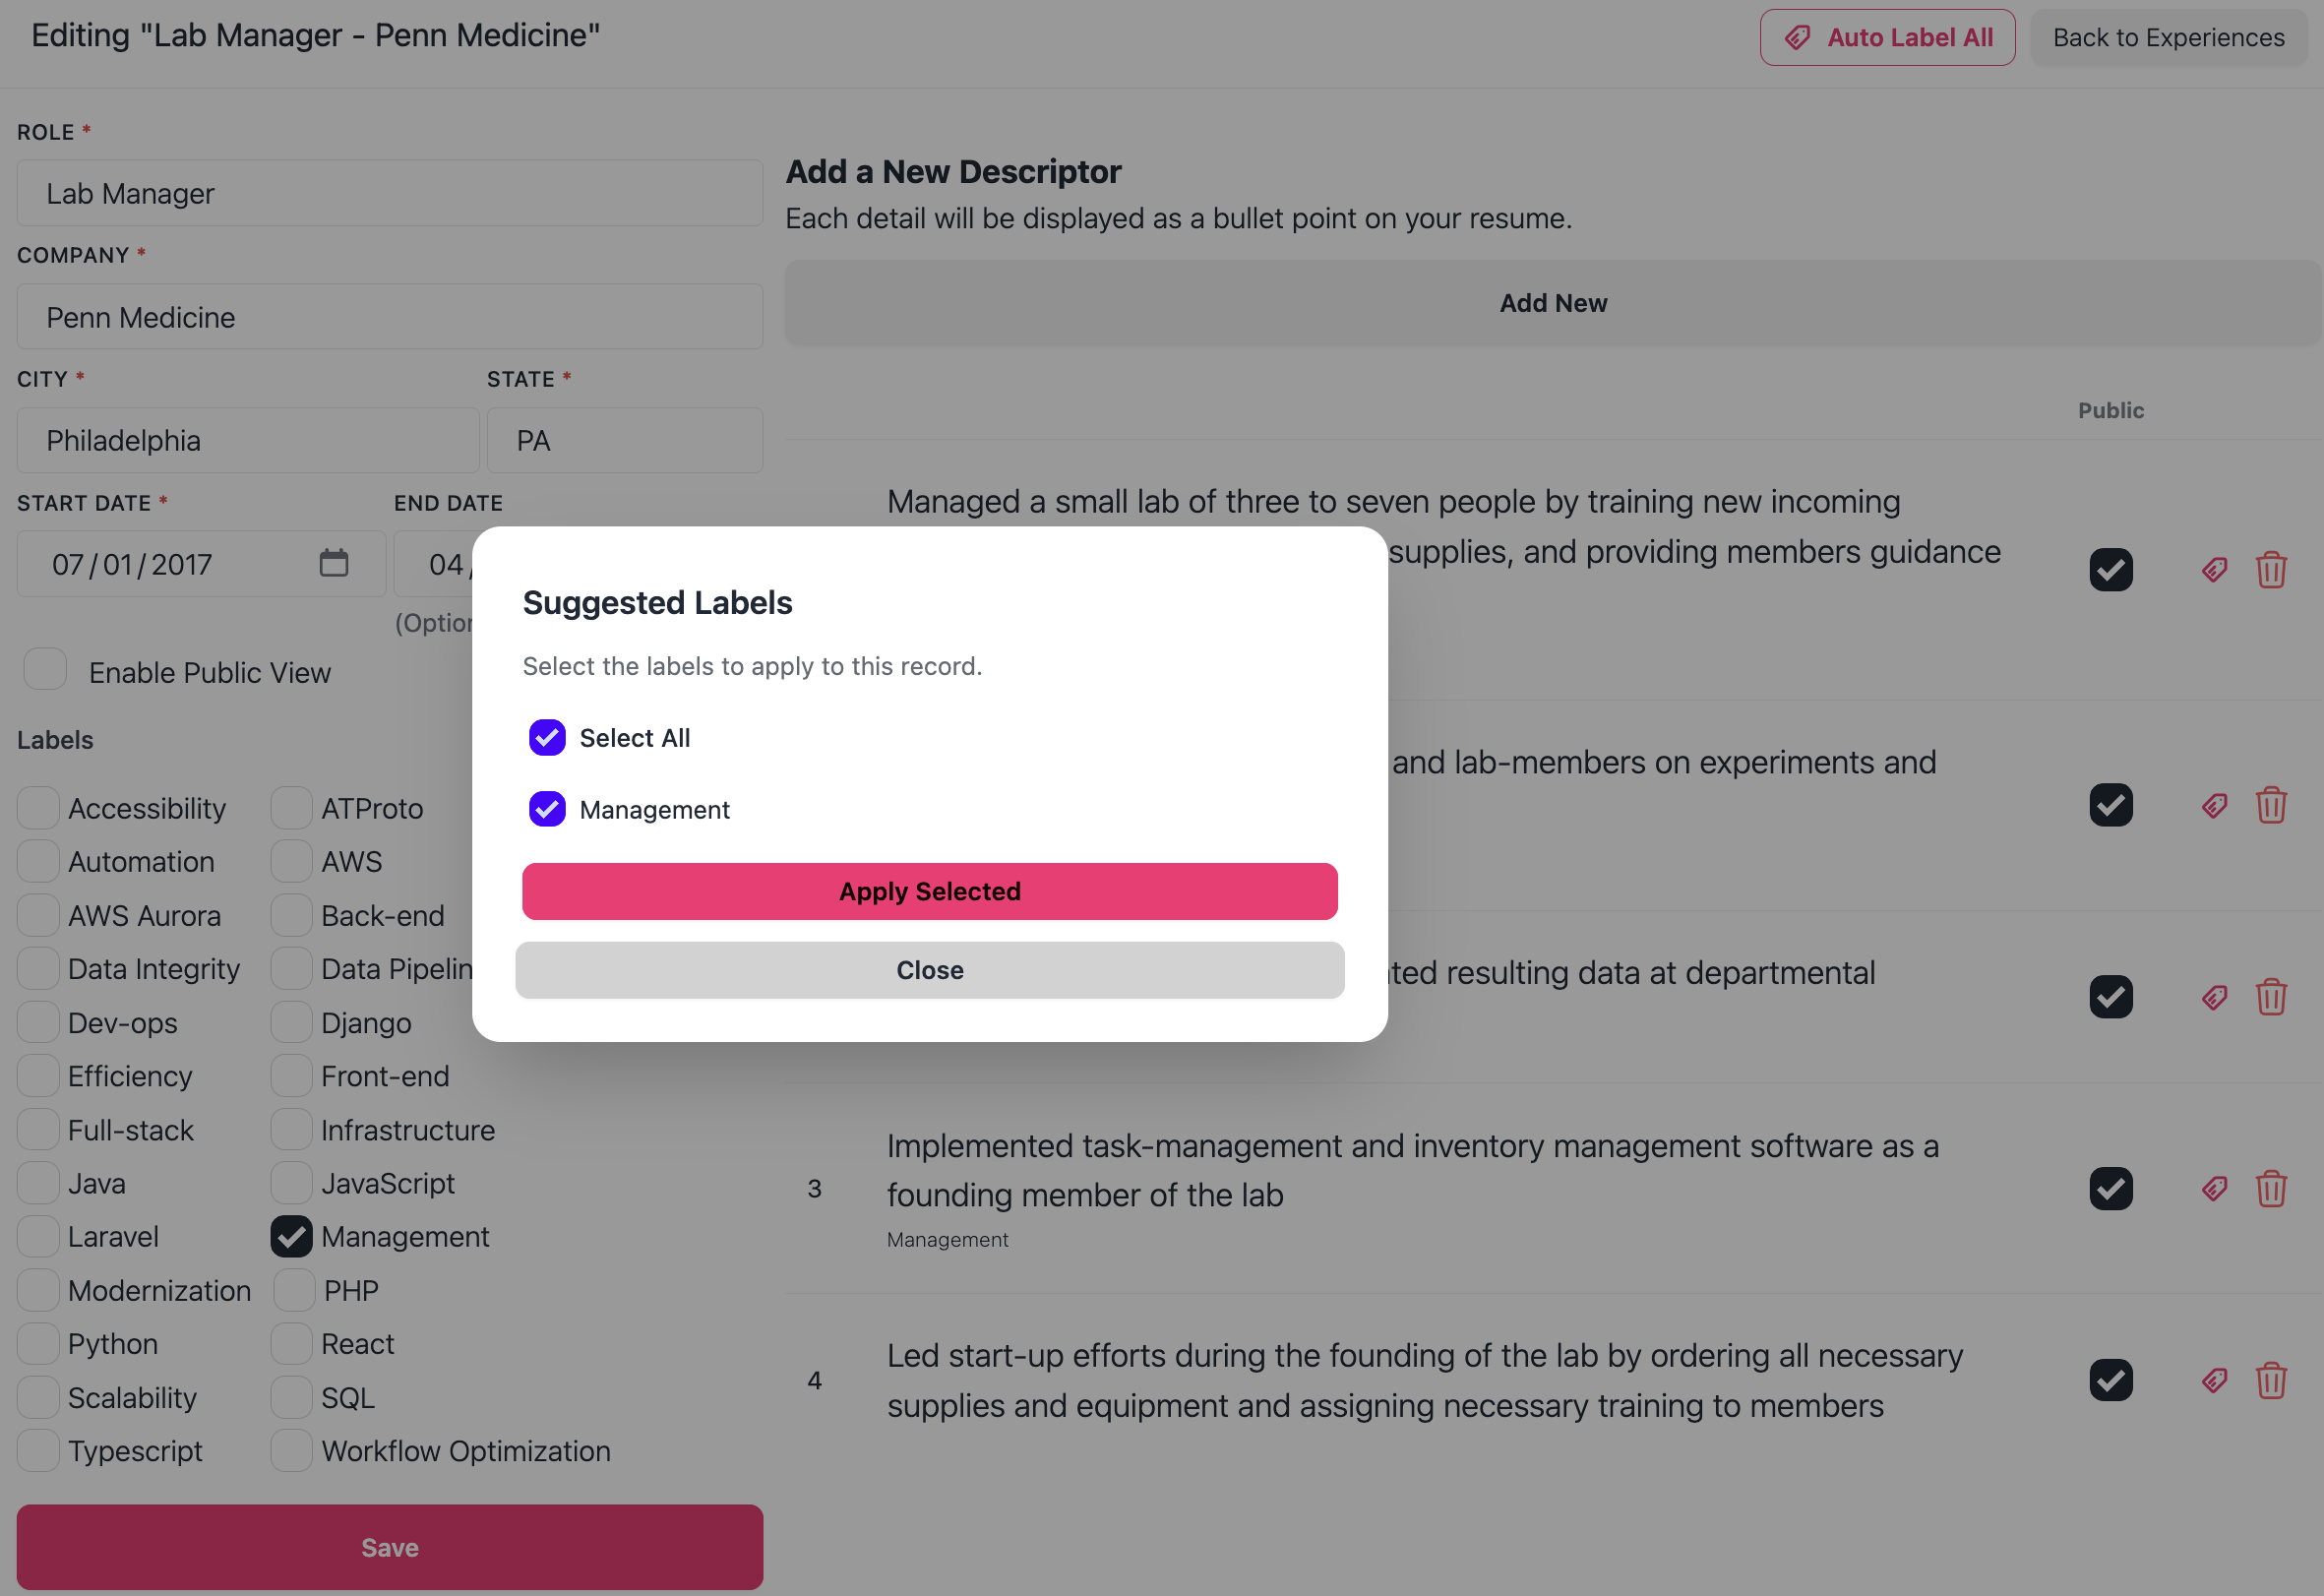
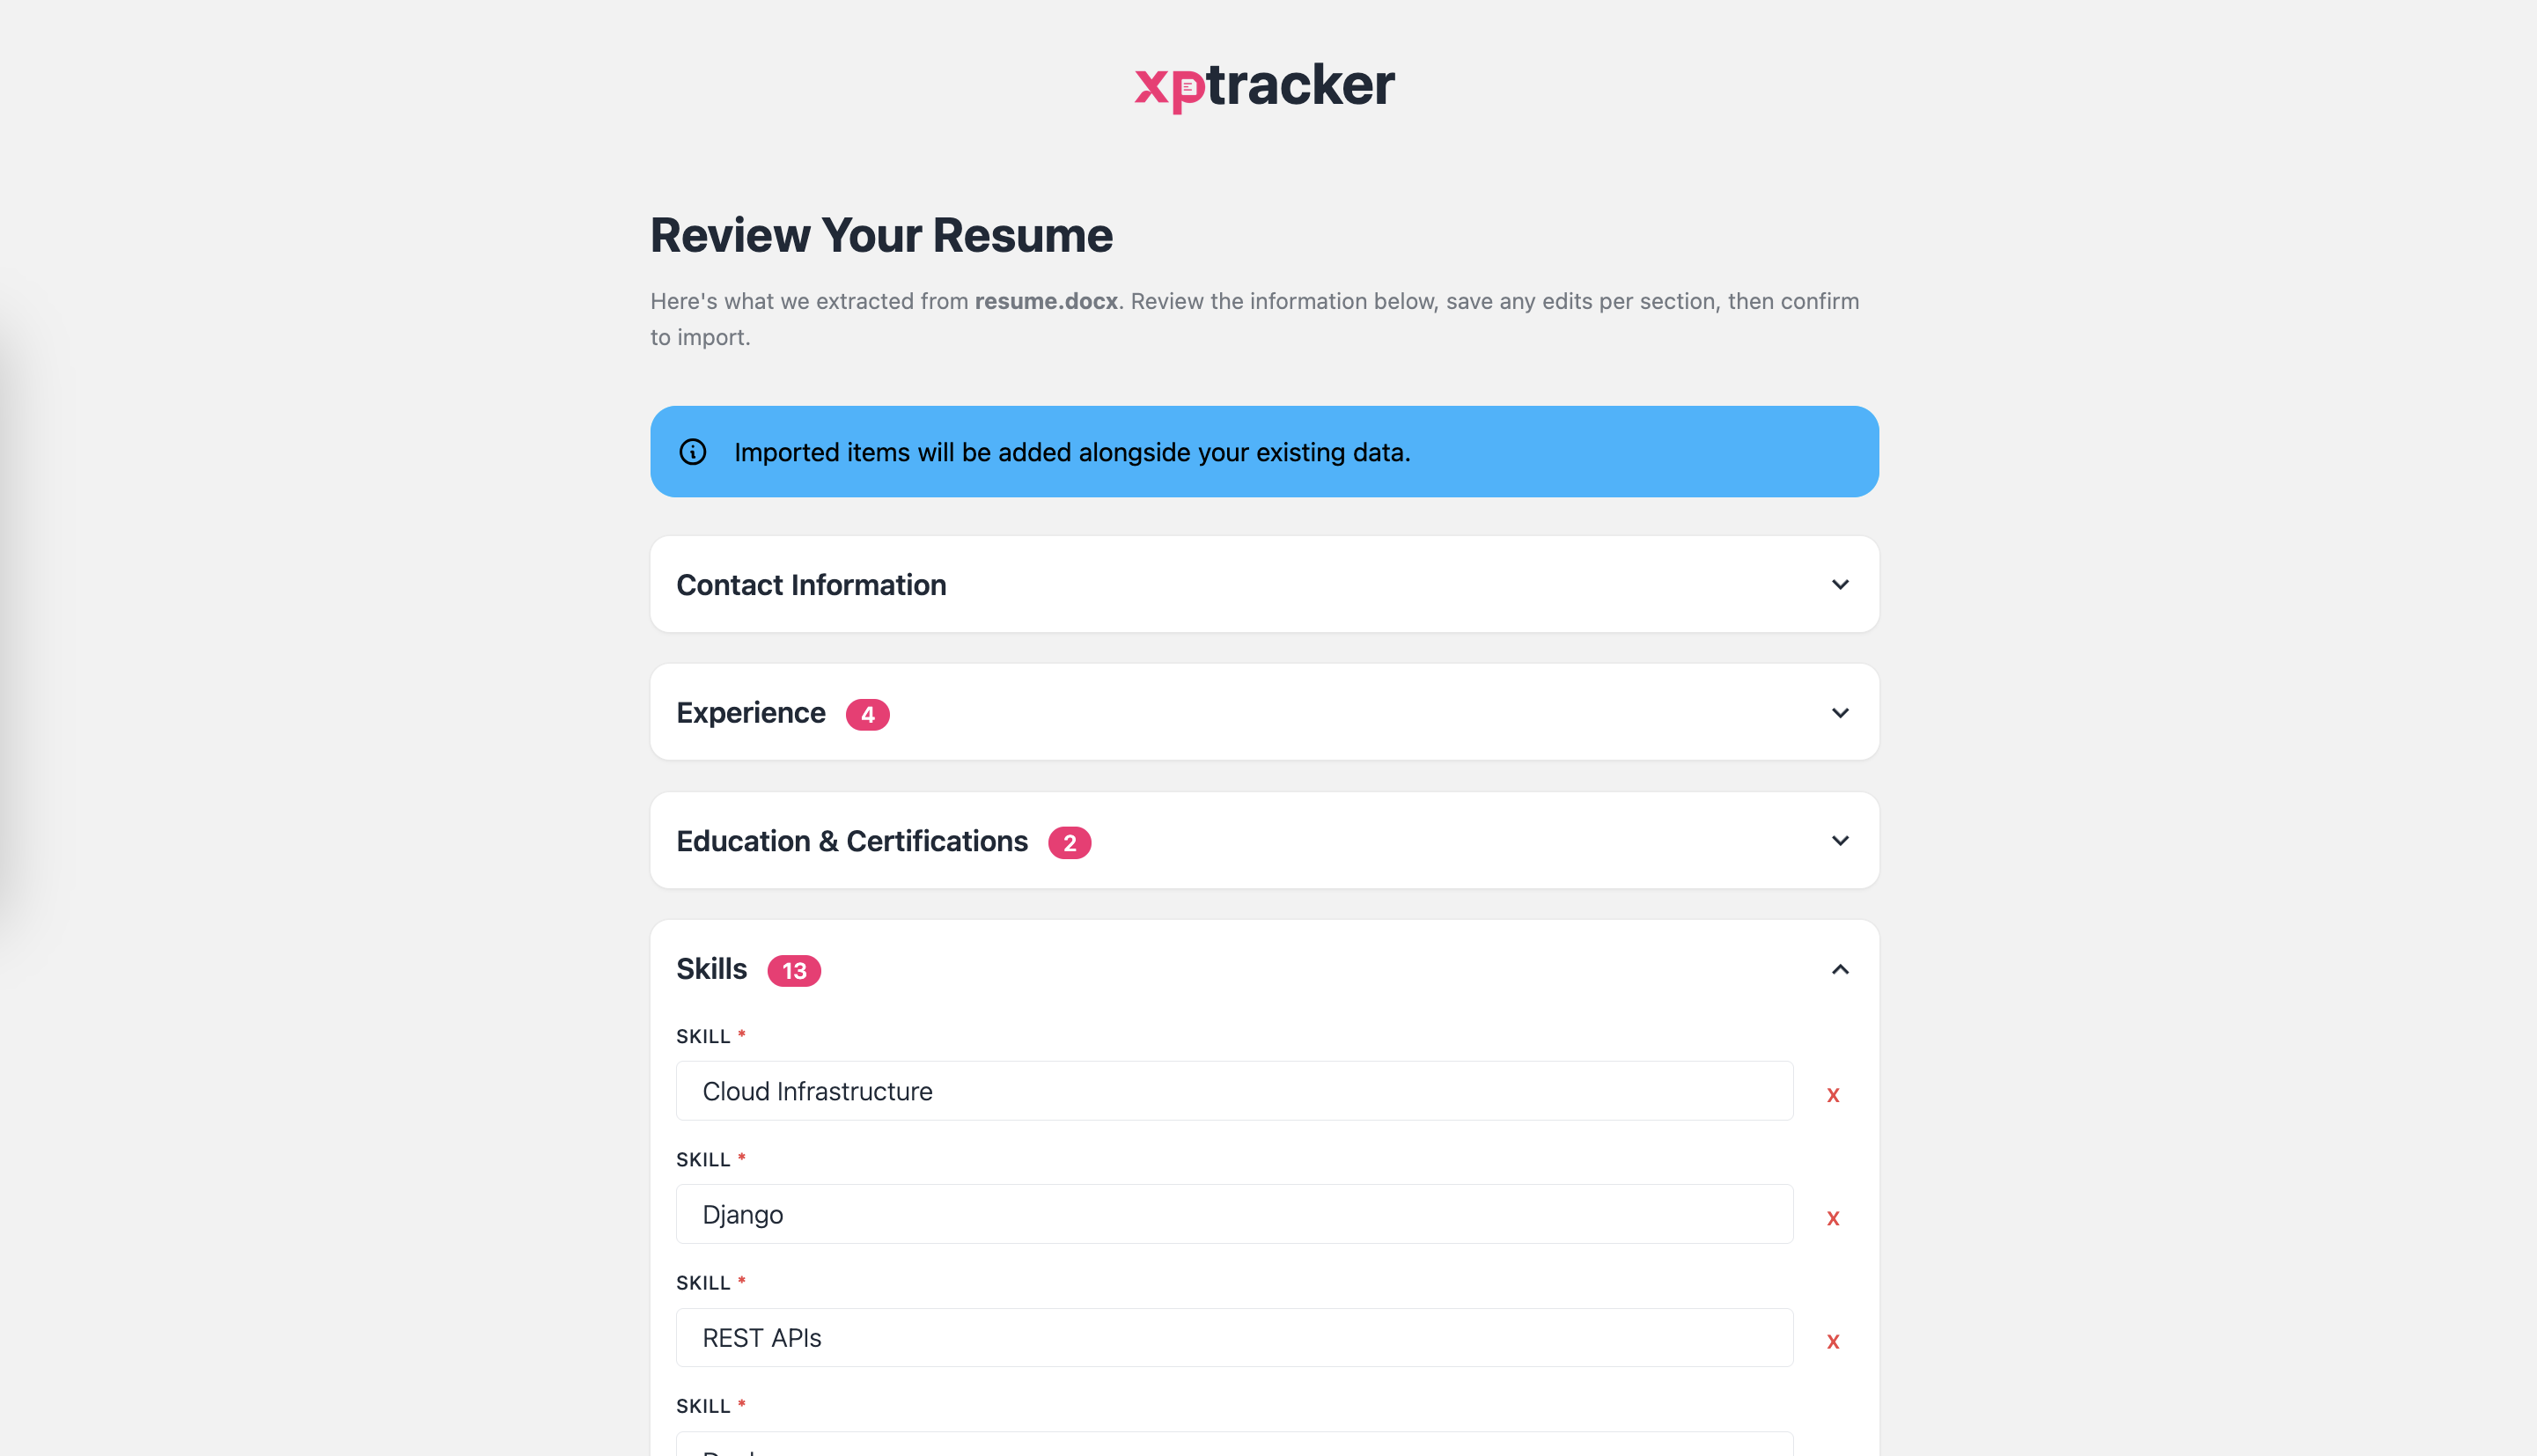
Resume Parsing

Introduced the new more welcoming onboarding workflow to xptracker, including the option to automatically parse an uploaded resume.

Entry image Entry image Entry image

ATProto Django Integration

Integrated the ATProto authentication protocol to allow users to link their Bluesky profiles to xptracker. Used newly linked profiles to allow users to share their career journal entries directly to Bluesky. All this in preparation for more features to come.

Satellite Data Processing

Created multiple data pipe-lines to download satellite datasets for sea surface temperature. Including creating pipelines that run on an hourly, daily, and weekly basis. Processed raw NetCDF4 files into GeoTIFFs, projected data over web mercator map format, and pushed to custom WMS tile-hosting solution hosted via AWS S3.

Implemented a custom tiling layer using Leaflet JS that displayed data using customizable color ranges, and on-hover temperature reading functionality.