Depth Data Mapping & Processing
This past week I've been working with our data store at Canyon Runner to collect and process boat depth sensor readings from our fleet of boats.
Purpose
This work is preliminary research to determine if we have enough data to provide more real-time depth readouts and charts for our customers. The aim here is to provide more real time charting for inlets that often have rapidly changing underwater conditions after storm surges.
Approach
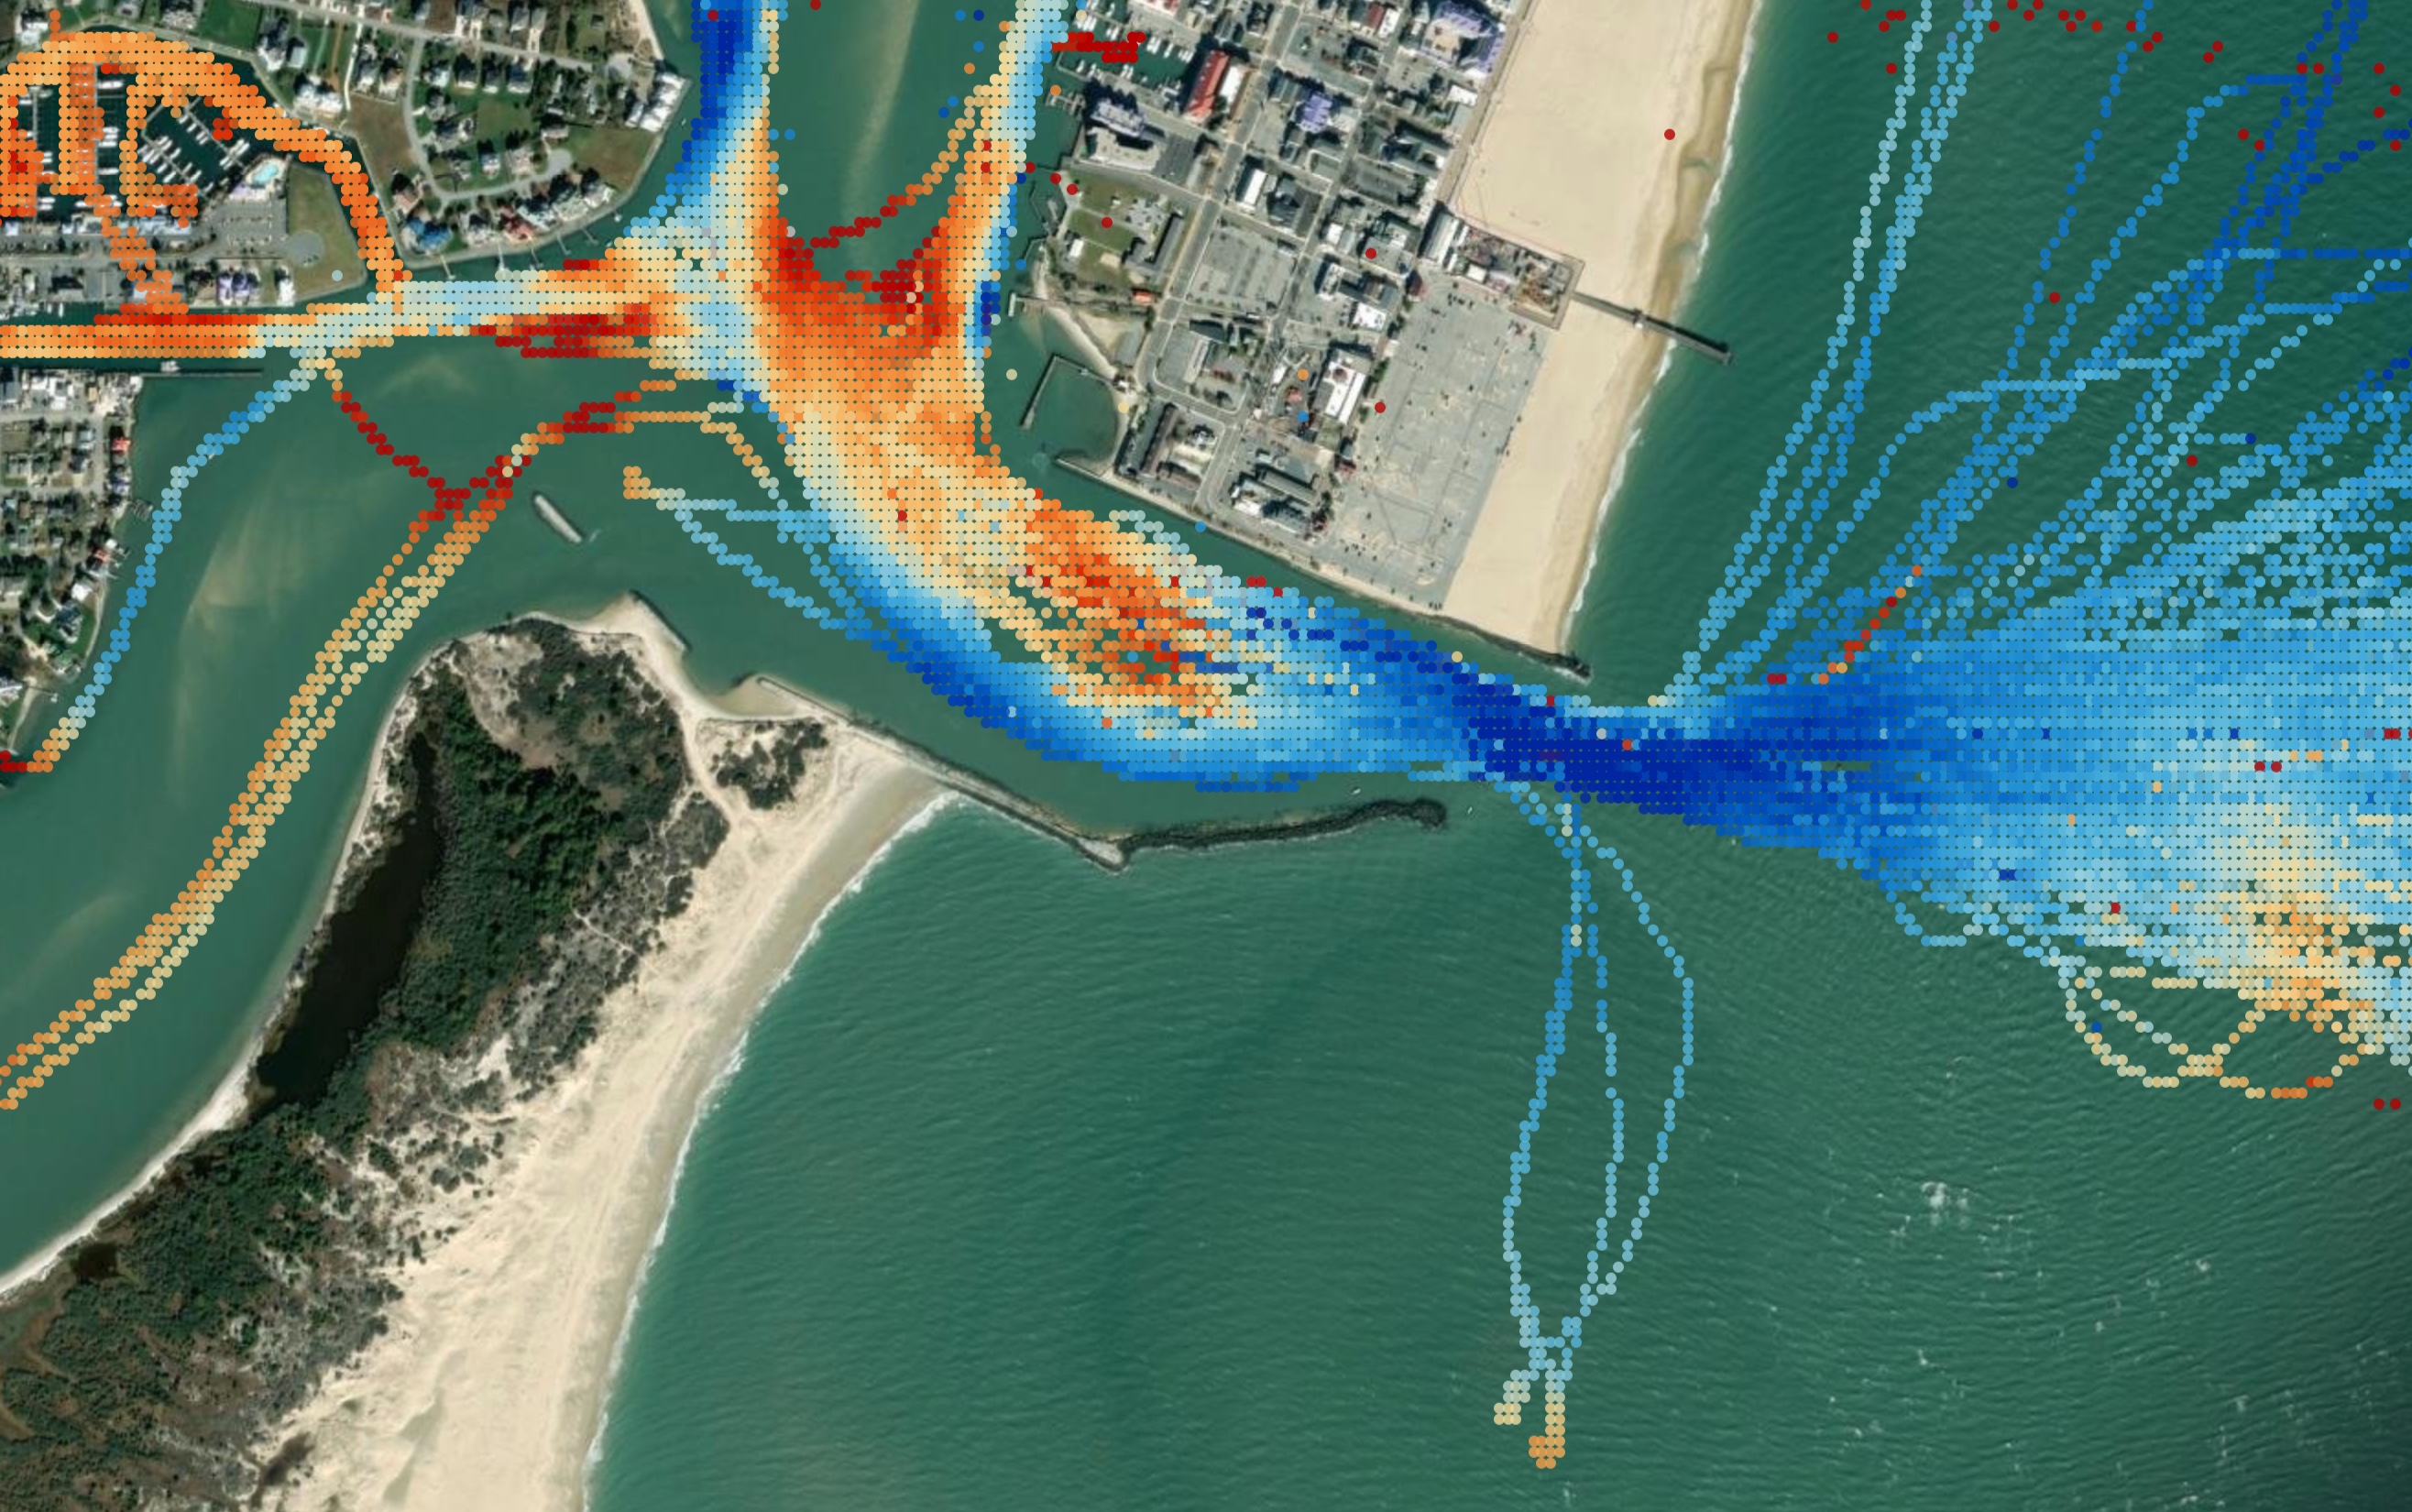
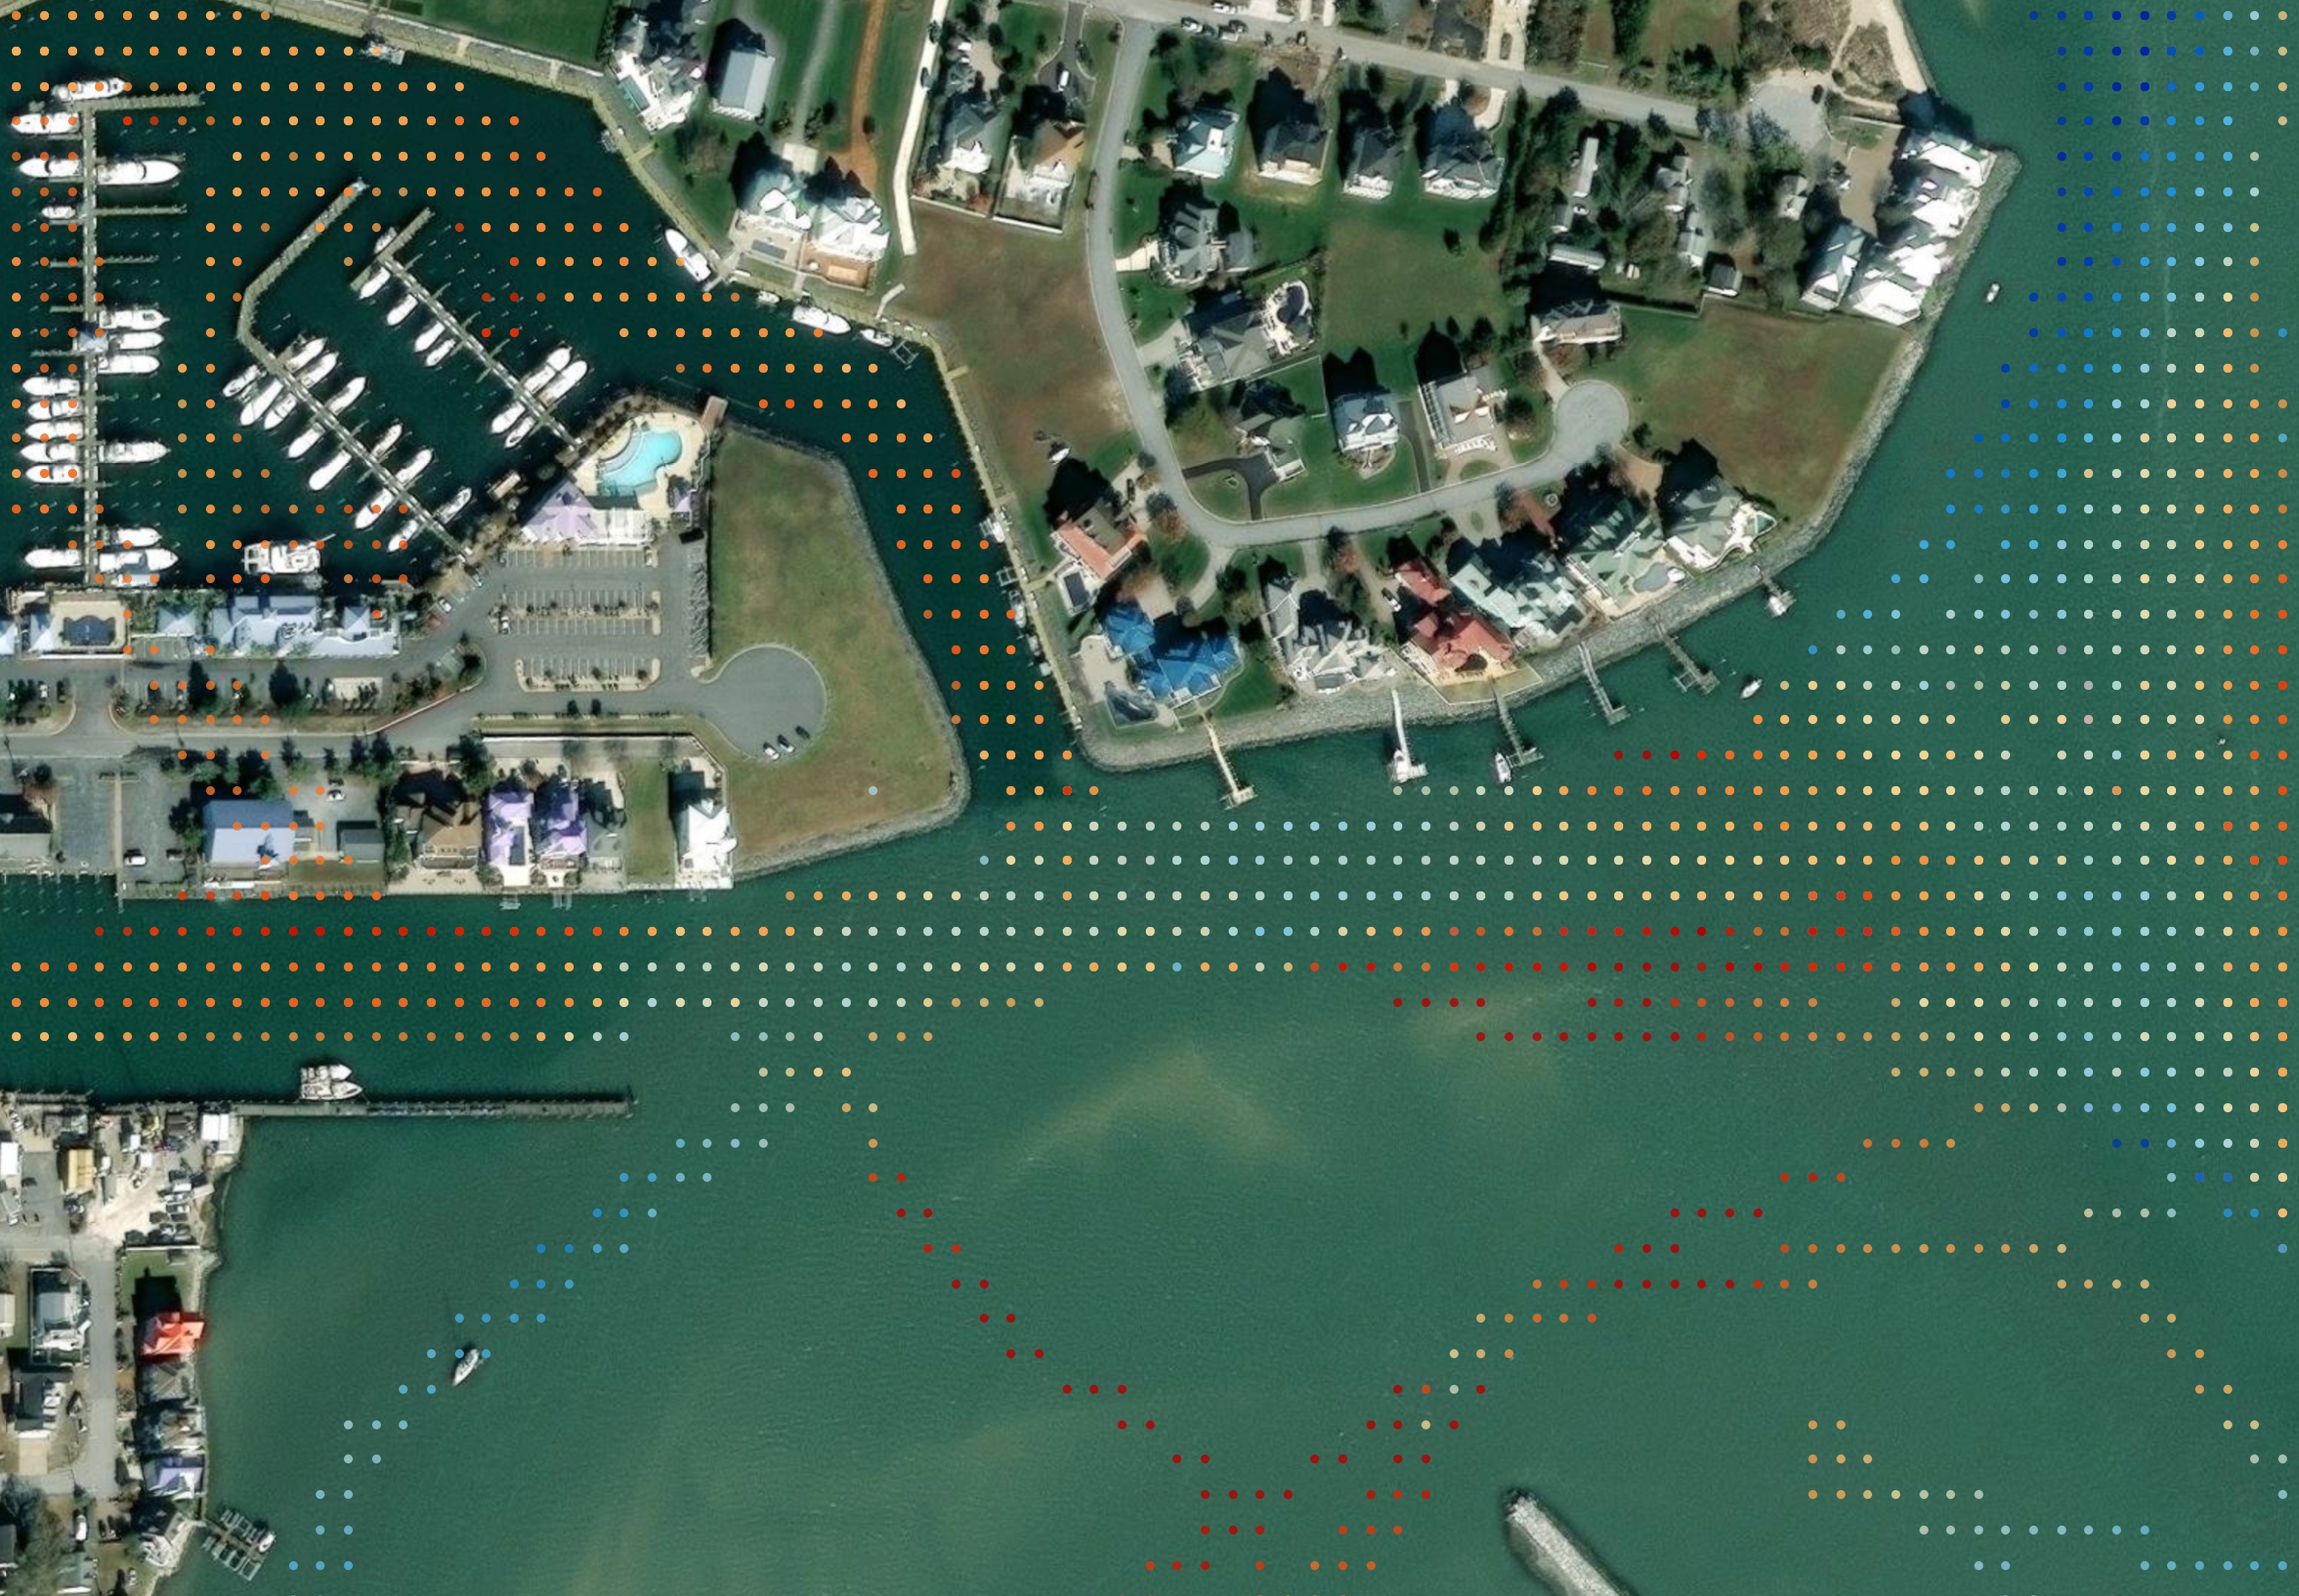
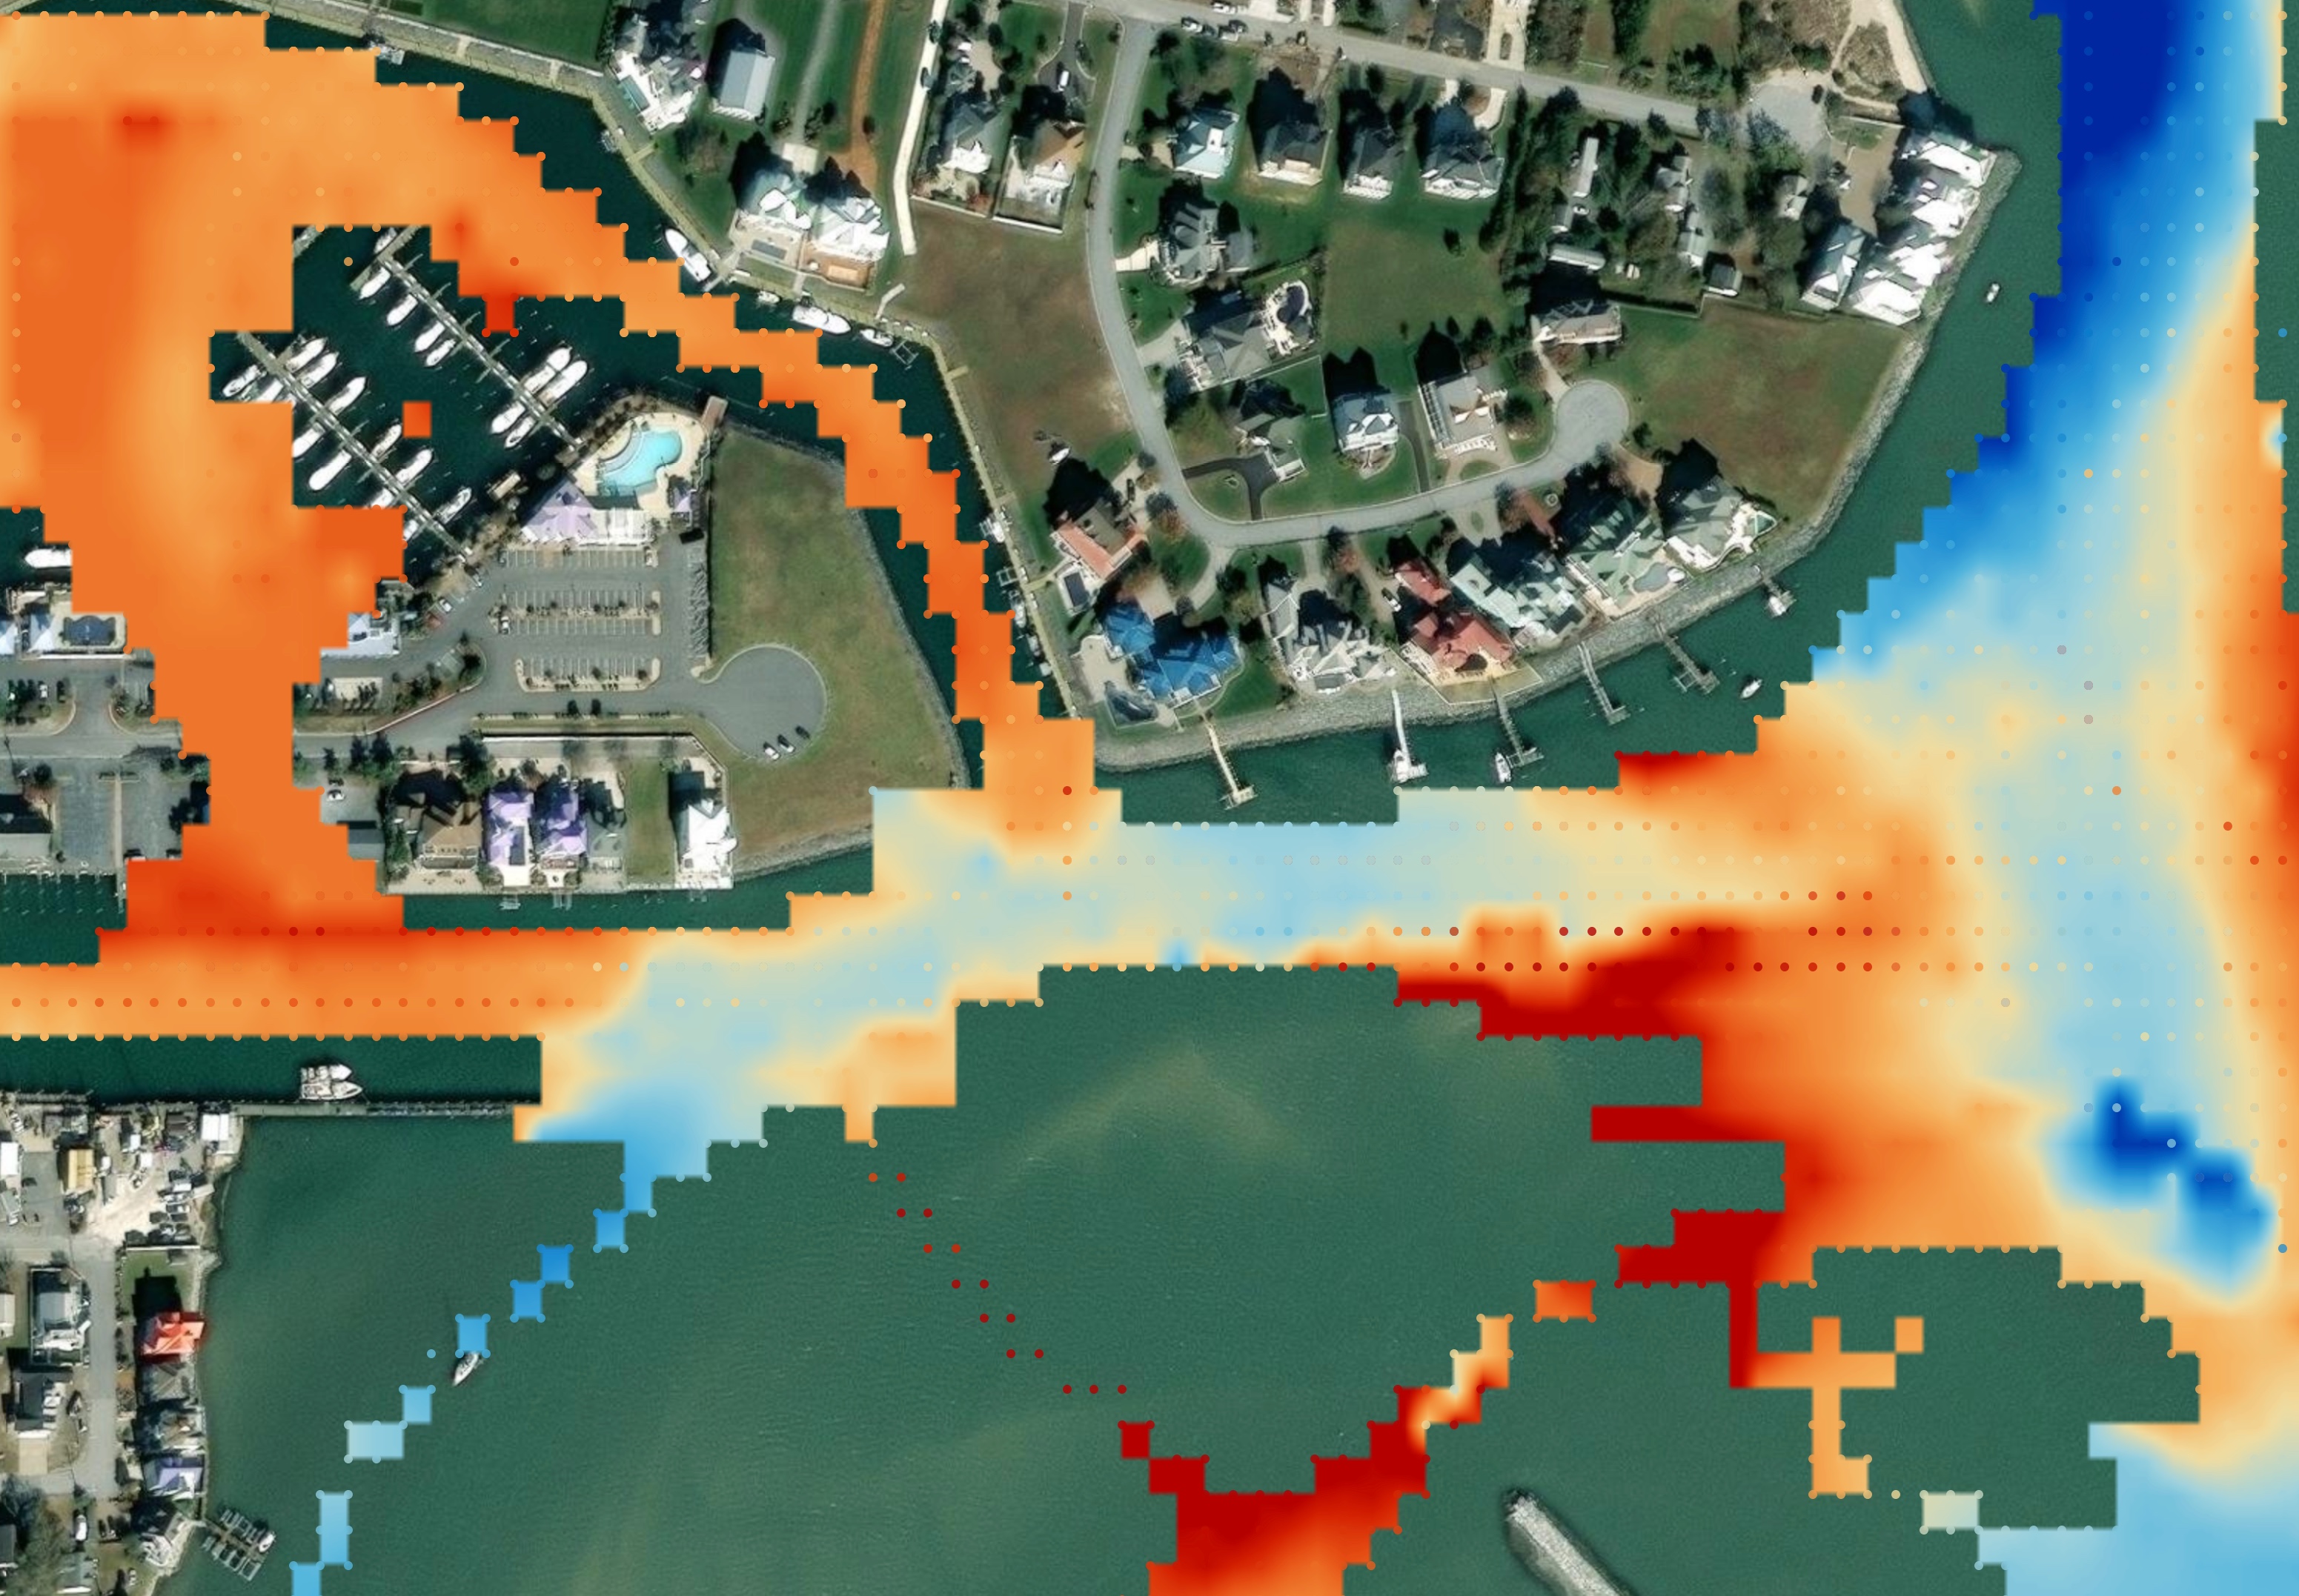
The approach here requires mapping our depth sensor readouts (which don't come with geo-coordinates) to the boats coordinate readouts aligned by time, with a sliding window of four seconds (an arbitrary time chosen to prevent data loss while still maintaining accuracy). These points then get mapped to a grid for consistency (see screenshots), and the median value is displayed and interpolated to create a relief chart.
This work is still ongoing, and is predominantly just research to see how feasible using this data will be to provide customers with more up-to-date depth readouts.
By the Numbers
A single inlet across a 6-month time span might have anywhere from 4-12 million data points depending on how much traffic is passing through that inlet. The goal here is to make it render on a map, while offering various data filters, and still keeping it performant.